Why Claude Code Costs So Much
You're probably spending 2-3x more than you need to. Here's where the money goes and what to do about it. Special section for Claude Code Max & Pro subscribers.
~8 min readThe $600/month Problem
If you're using Claude Code daily, you've probably noticed: the bill adds up fast. A normal day of coding with Sonnet can cost $4-12. Heavy refactoring or agent-heavy sessions can hit $25+. Multiply by a month, and you're looking at $100-600 depending on how you work.
The frustrating part? Most of that cost is waste. You're paying full price for the same text, your project context, your settings, your tool definitions, on every single request. The API supports ways to avoid this, but they require specific headers and configurations that Claude Code doesn't set up for you.
| Scenario | What you pay today | What you should pay |
|---|---|---|
| Light day (50 requests) | ~$2.00 | ~$0.70 |
| Normal day (150 requests) | ~$4.50 | ~$1.50 |
| Heavy refactoring | ~$12.00 | ~$4.00 |
| Agent-heavy session | ~$25.00 | ~$10.00 |
The gap between those two columns? That's money you don't have to spend.
Where It Actually Goes
Every time you send a message in Claude Code, the API receives much more than your message. It receives your entire project context, conversation history, tool definitions, and any files Claude has read, all over again. You pay for every token, every time.
The biggest cost drivers
- Repeated project context, your CLAUDE.md and settings are sent with every request. If your project context is 2,000 tokens and you make 200 requests/day, that's 400,000 tokens of identical text you're paying full price for.
- Conversation history snowball, by turn 20, you're sending 50,000+ tokens of old messages. By turn 30, it's 140,000+. Each turn is more expensive than the last.
- MCP tool definitions, every MCP server you have installed contributes its full schema on every request. A few servers can add 50,000 tokens before Claude reads a single word you typed.
- Agent multiplication, sub-agents each start fresh with the full context. Three agents doing research = 3x the cost of one request.
Up to 80% of your input tokens on every request are identical repeated text. The API has ways to handle this cheaply, but the setup is complex and error-prone. Most developers never bother, and overpay by 2-3x as a result.
What You Can Do Today (Free)
These habits reduce your bill immediately, no tools needed:
- Use /clear between tasks, the single biggest saving. A fresh conversation costs a fraction of a 30-turn one. Switch topics? Clear first.
- Point Claude to specific files, "look at src/auth.ts" costs one file. "look at my code" costs ten. Be specific.
- Keep your CLAUDE.md lean, every word is sent on every request. If Claude would behave the same without a line, delete it.
- Remove MCP servers you don't use daily, they add token overhead to every request even when you don't call them.
- Ask for a plan before asking for code, reviewing a $0.05 plan is cheaper than undoing a $2.00 implementation that went the wrong way.
Good habits can save 15-25%. But you have to remember to do them every time, and they don't address the core issue: repeated context being billed at full price.
What You Can't Do Manually
The API supports optimizations that can cut your bill substantially (how much depends entirely on your workload, which is why the dashboard shows you the honest, per-request number rather than a headline percentage). But they require intercepting every request, modifying headers, analyzing prompt content, and making routing decisions in real time. This isn't something you can do from Claude Code's settings.
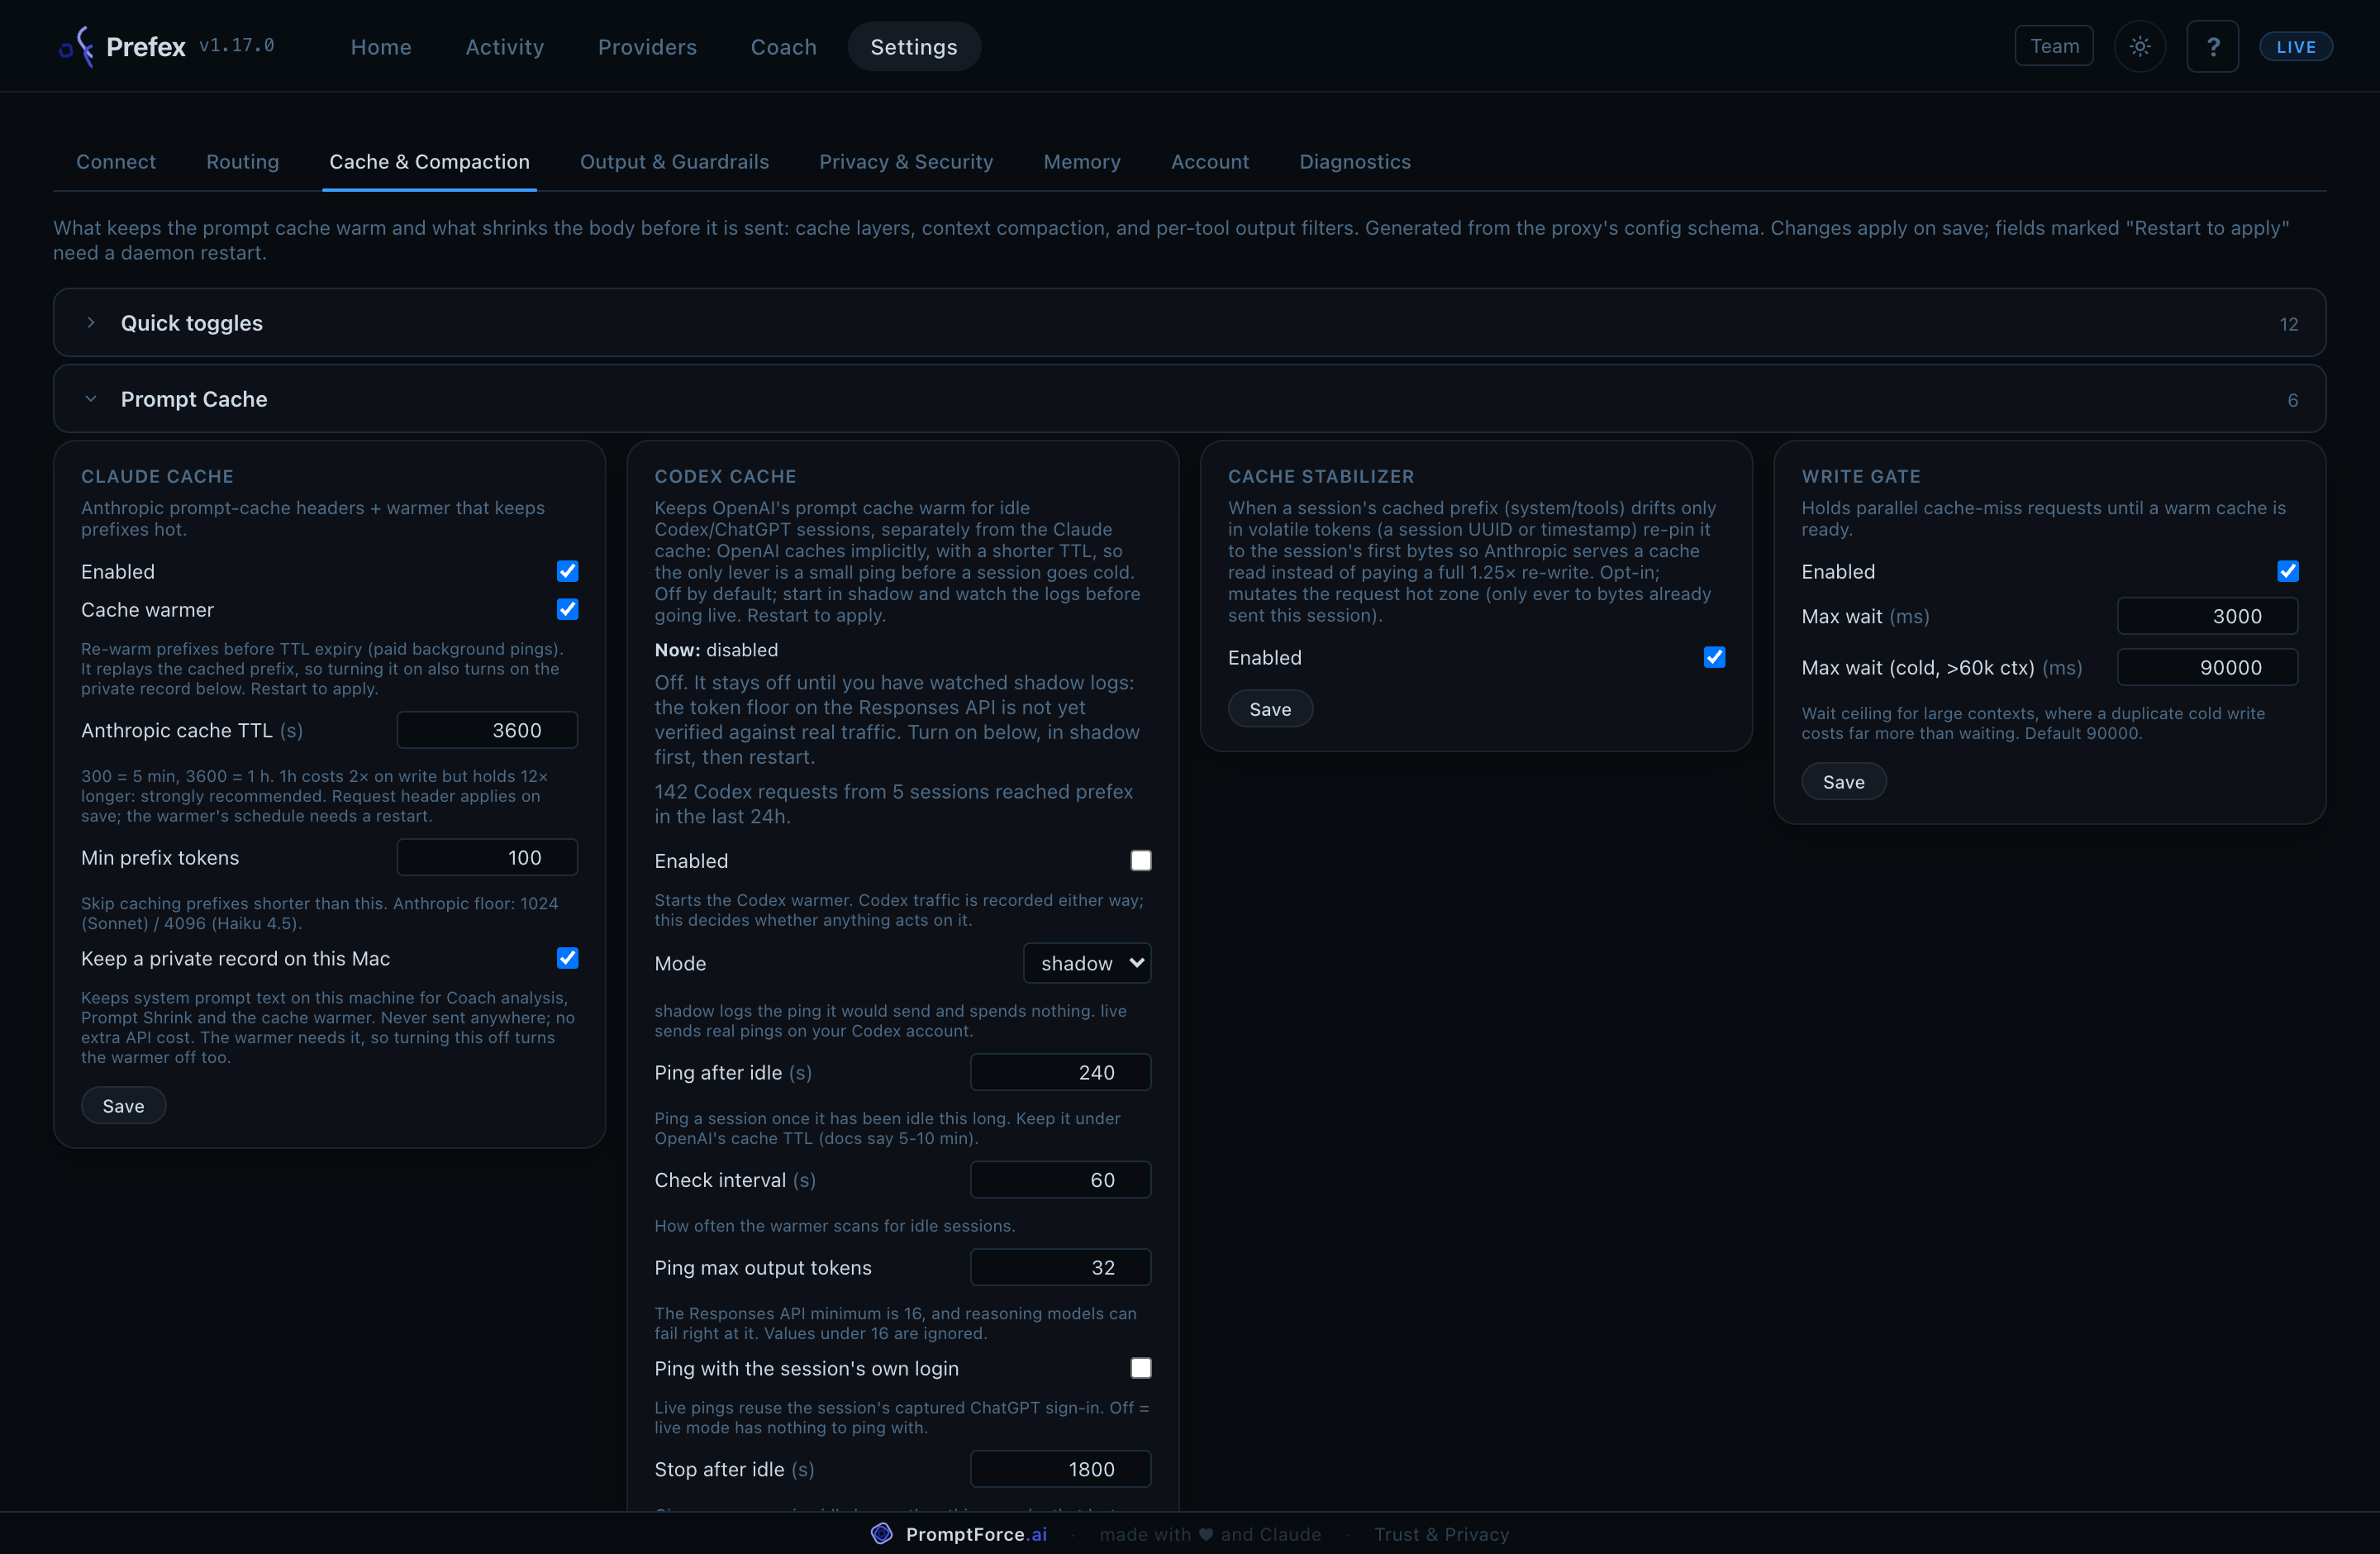
Anthropic's prompt cache is real and powerful: cached tokens cost 0.1× the normal rate. But to use it, every request must include explicit cache_control markers in the right places. Without them, nothing gets cached. And even when headers are present, the cache expires after 5 minutes of idle and resets whenever you switch models, including between Opus, Sonnet and Haiku. In practice this means every coffee break, every /model command, and every new terminal session starts from a cold cache, billing full price for your CLAUDE.md and system prompt again.
Prefex injects the headers, extends cache lifetime to 1 hour, keeps the cache warm between your requests, and routes with the active model in mind so a cheap-task shortcut doesn't blow up an expensive cached prefix.
The optimization stack
| Tier | Feature | What it does | Typical savings |
|---|---|---|---|
| Cost Reduction | Prompt Cache | Anthropic has built-in prompt caching, but it requires explicit cache_control headers and expires after 5 min of idle. Prefex injects the headers, extends TTL to 1 hour, and keeps the cache warm automatically. | 30–70% (varies by workload; the dashboard shows your measured figure) |
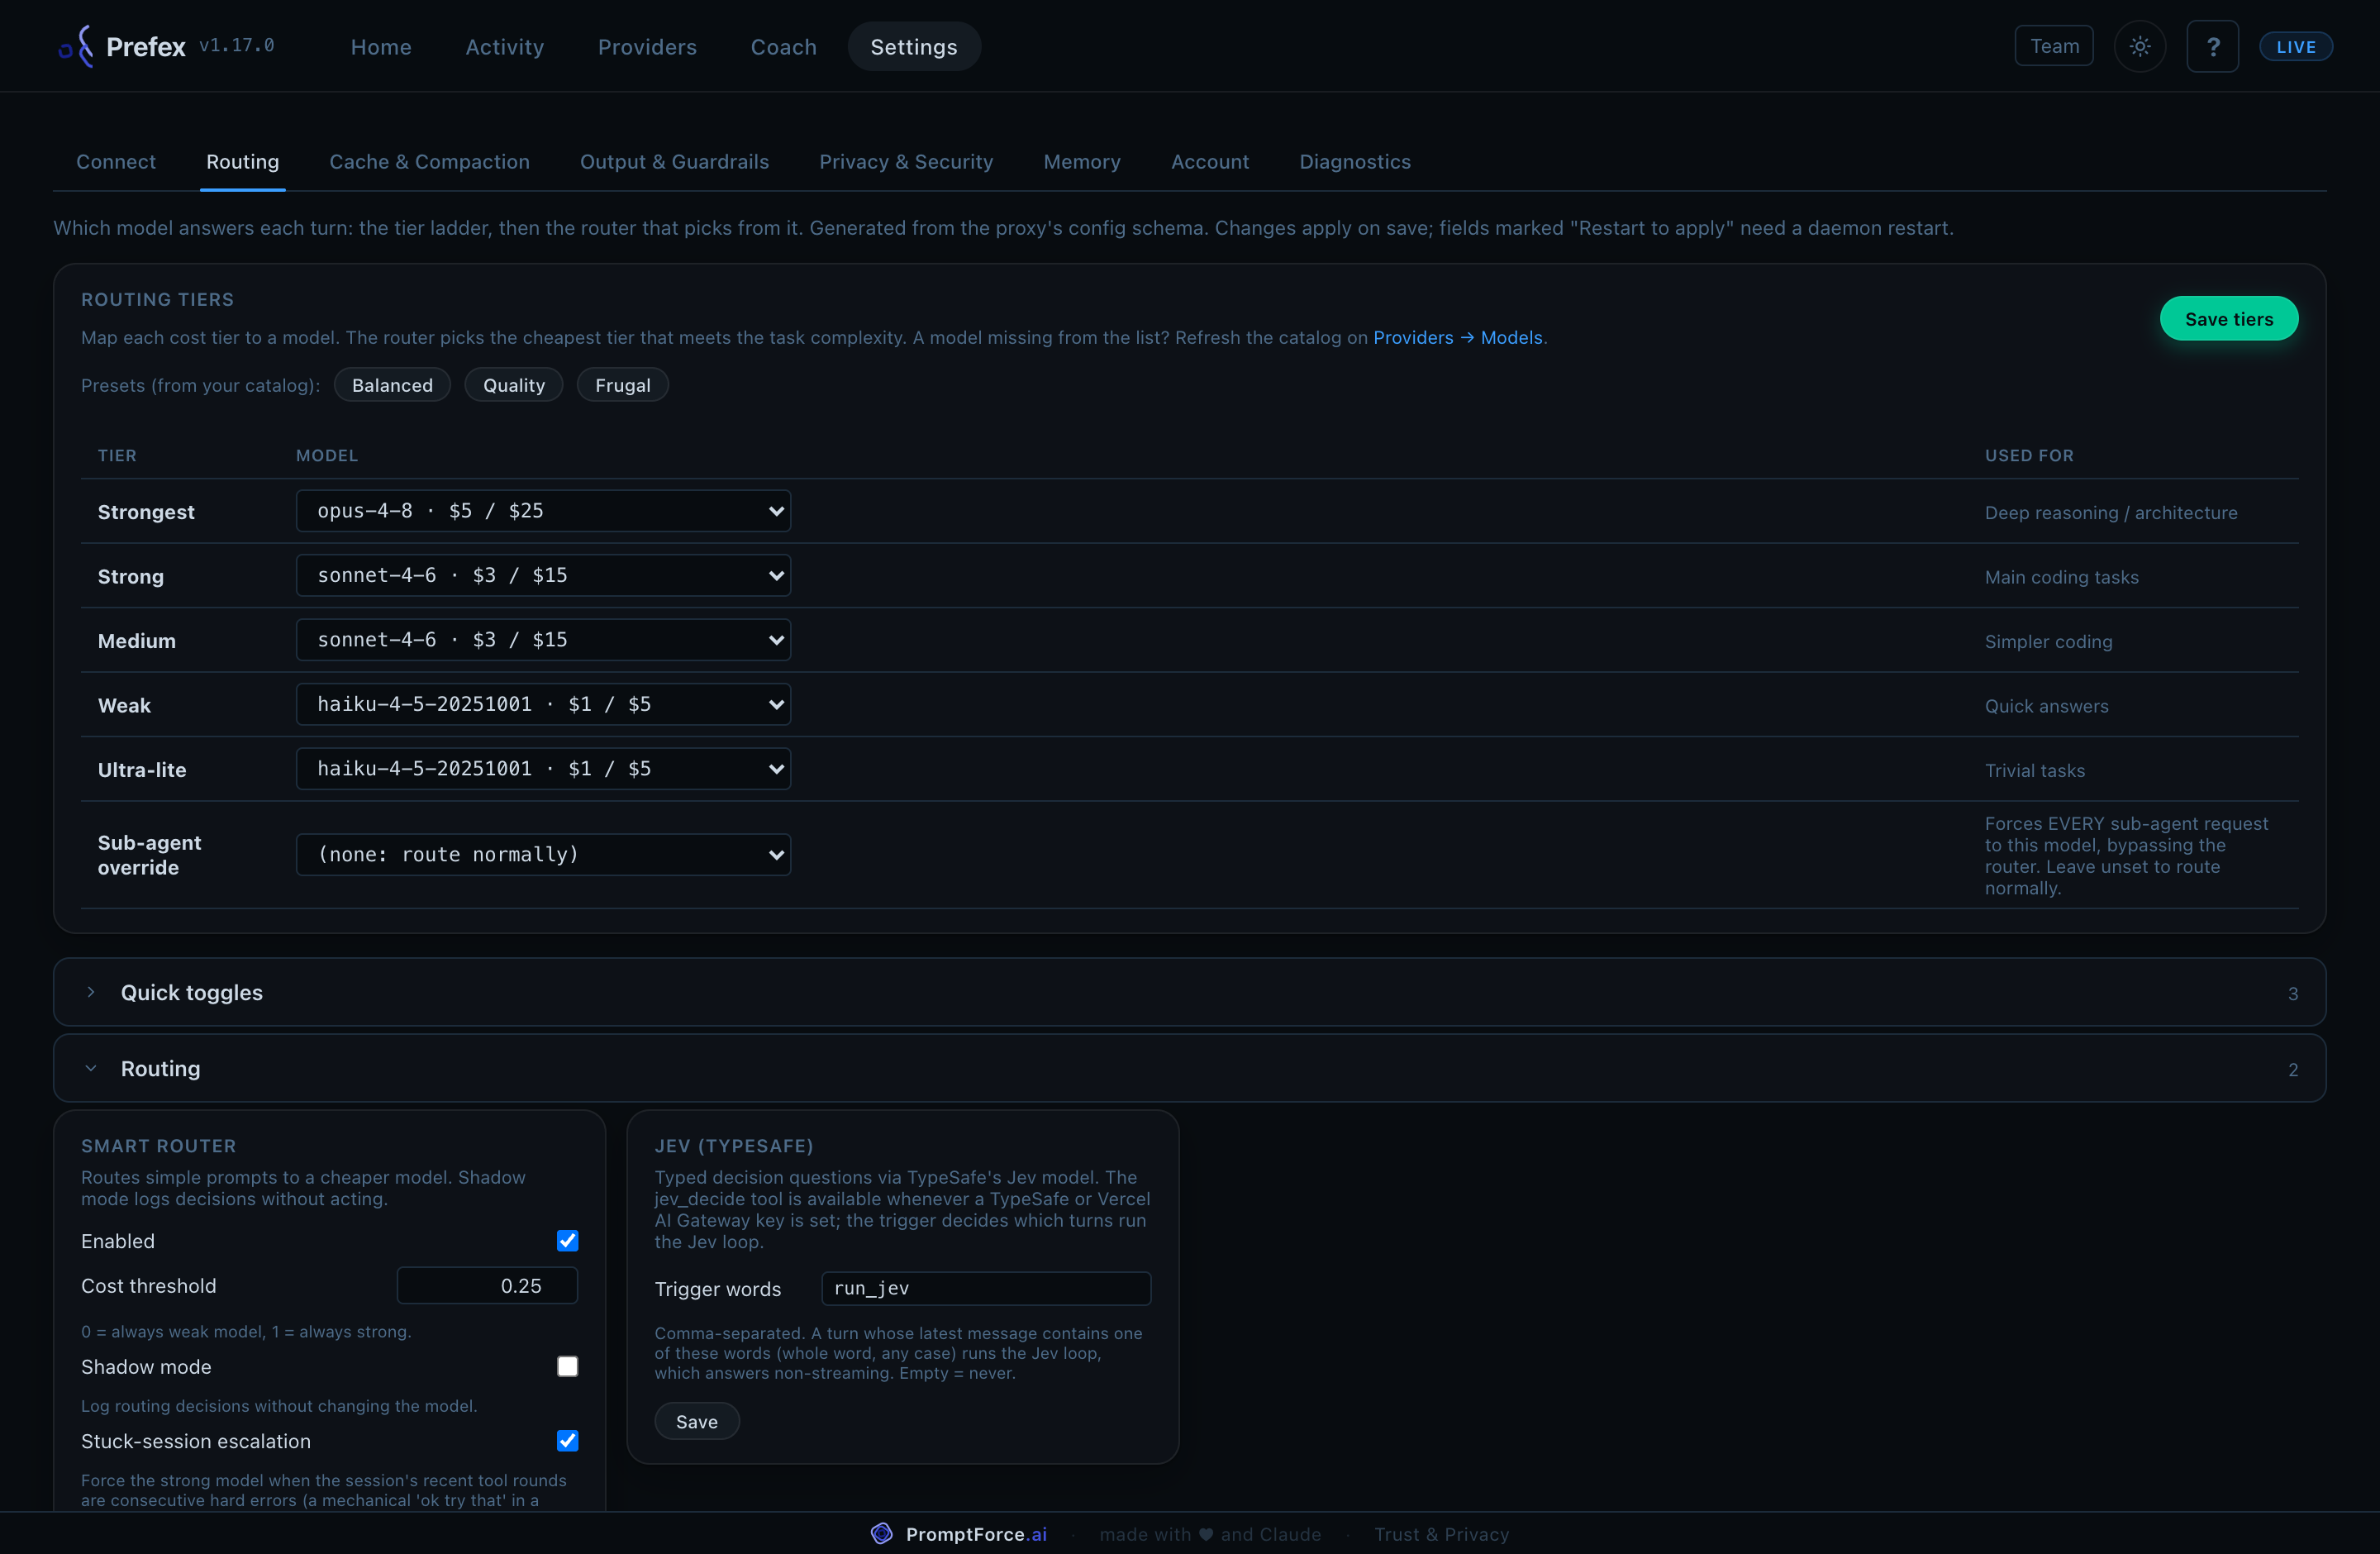
| Smart Router | Sends simple requests to Haiku automatically; routes complex ones to Sonnet/Opus. Validates the request body against the cheaper model before switching, so a downroute never breaks a request. | 10–30% | |
| Effort Routing | A second axis on the same model: the complexity score sets the reasoning effort level (low for simple turns, high for complex). Cache-safe and orthogonal to model routing. Opt-in, shadow-first. | refines cost | |
| Encoder Router | Optional on-device ModernBERT encoder that scores prompt complexity for sharper routing than rules alone. Runs fully offline; opt-in and default-off. | refines routing | |
| Compression | Compacts tool output by content type: JSON and CSV become lossless tables, grep/find results are grouped by directory, logs keep errors and first-seen lines, diffs trim context only, config and HTML lose comments and markup, and code keeps signatures while eliding bodies. Lossy compactions leave a marker the model can use to fetch the original back (prefex_recall). | varies; the dashboard reports it per mechanism | |
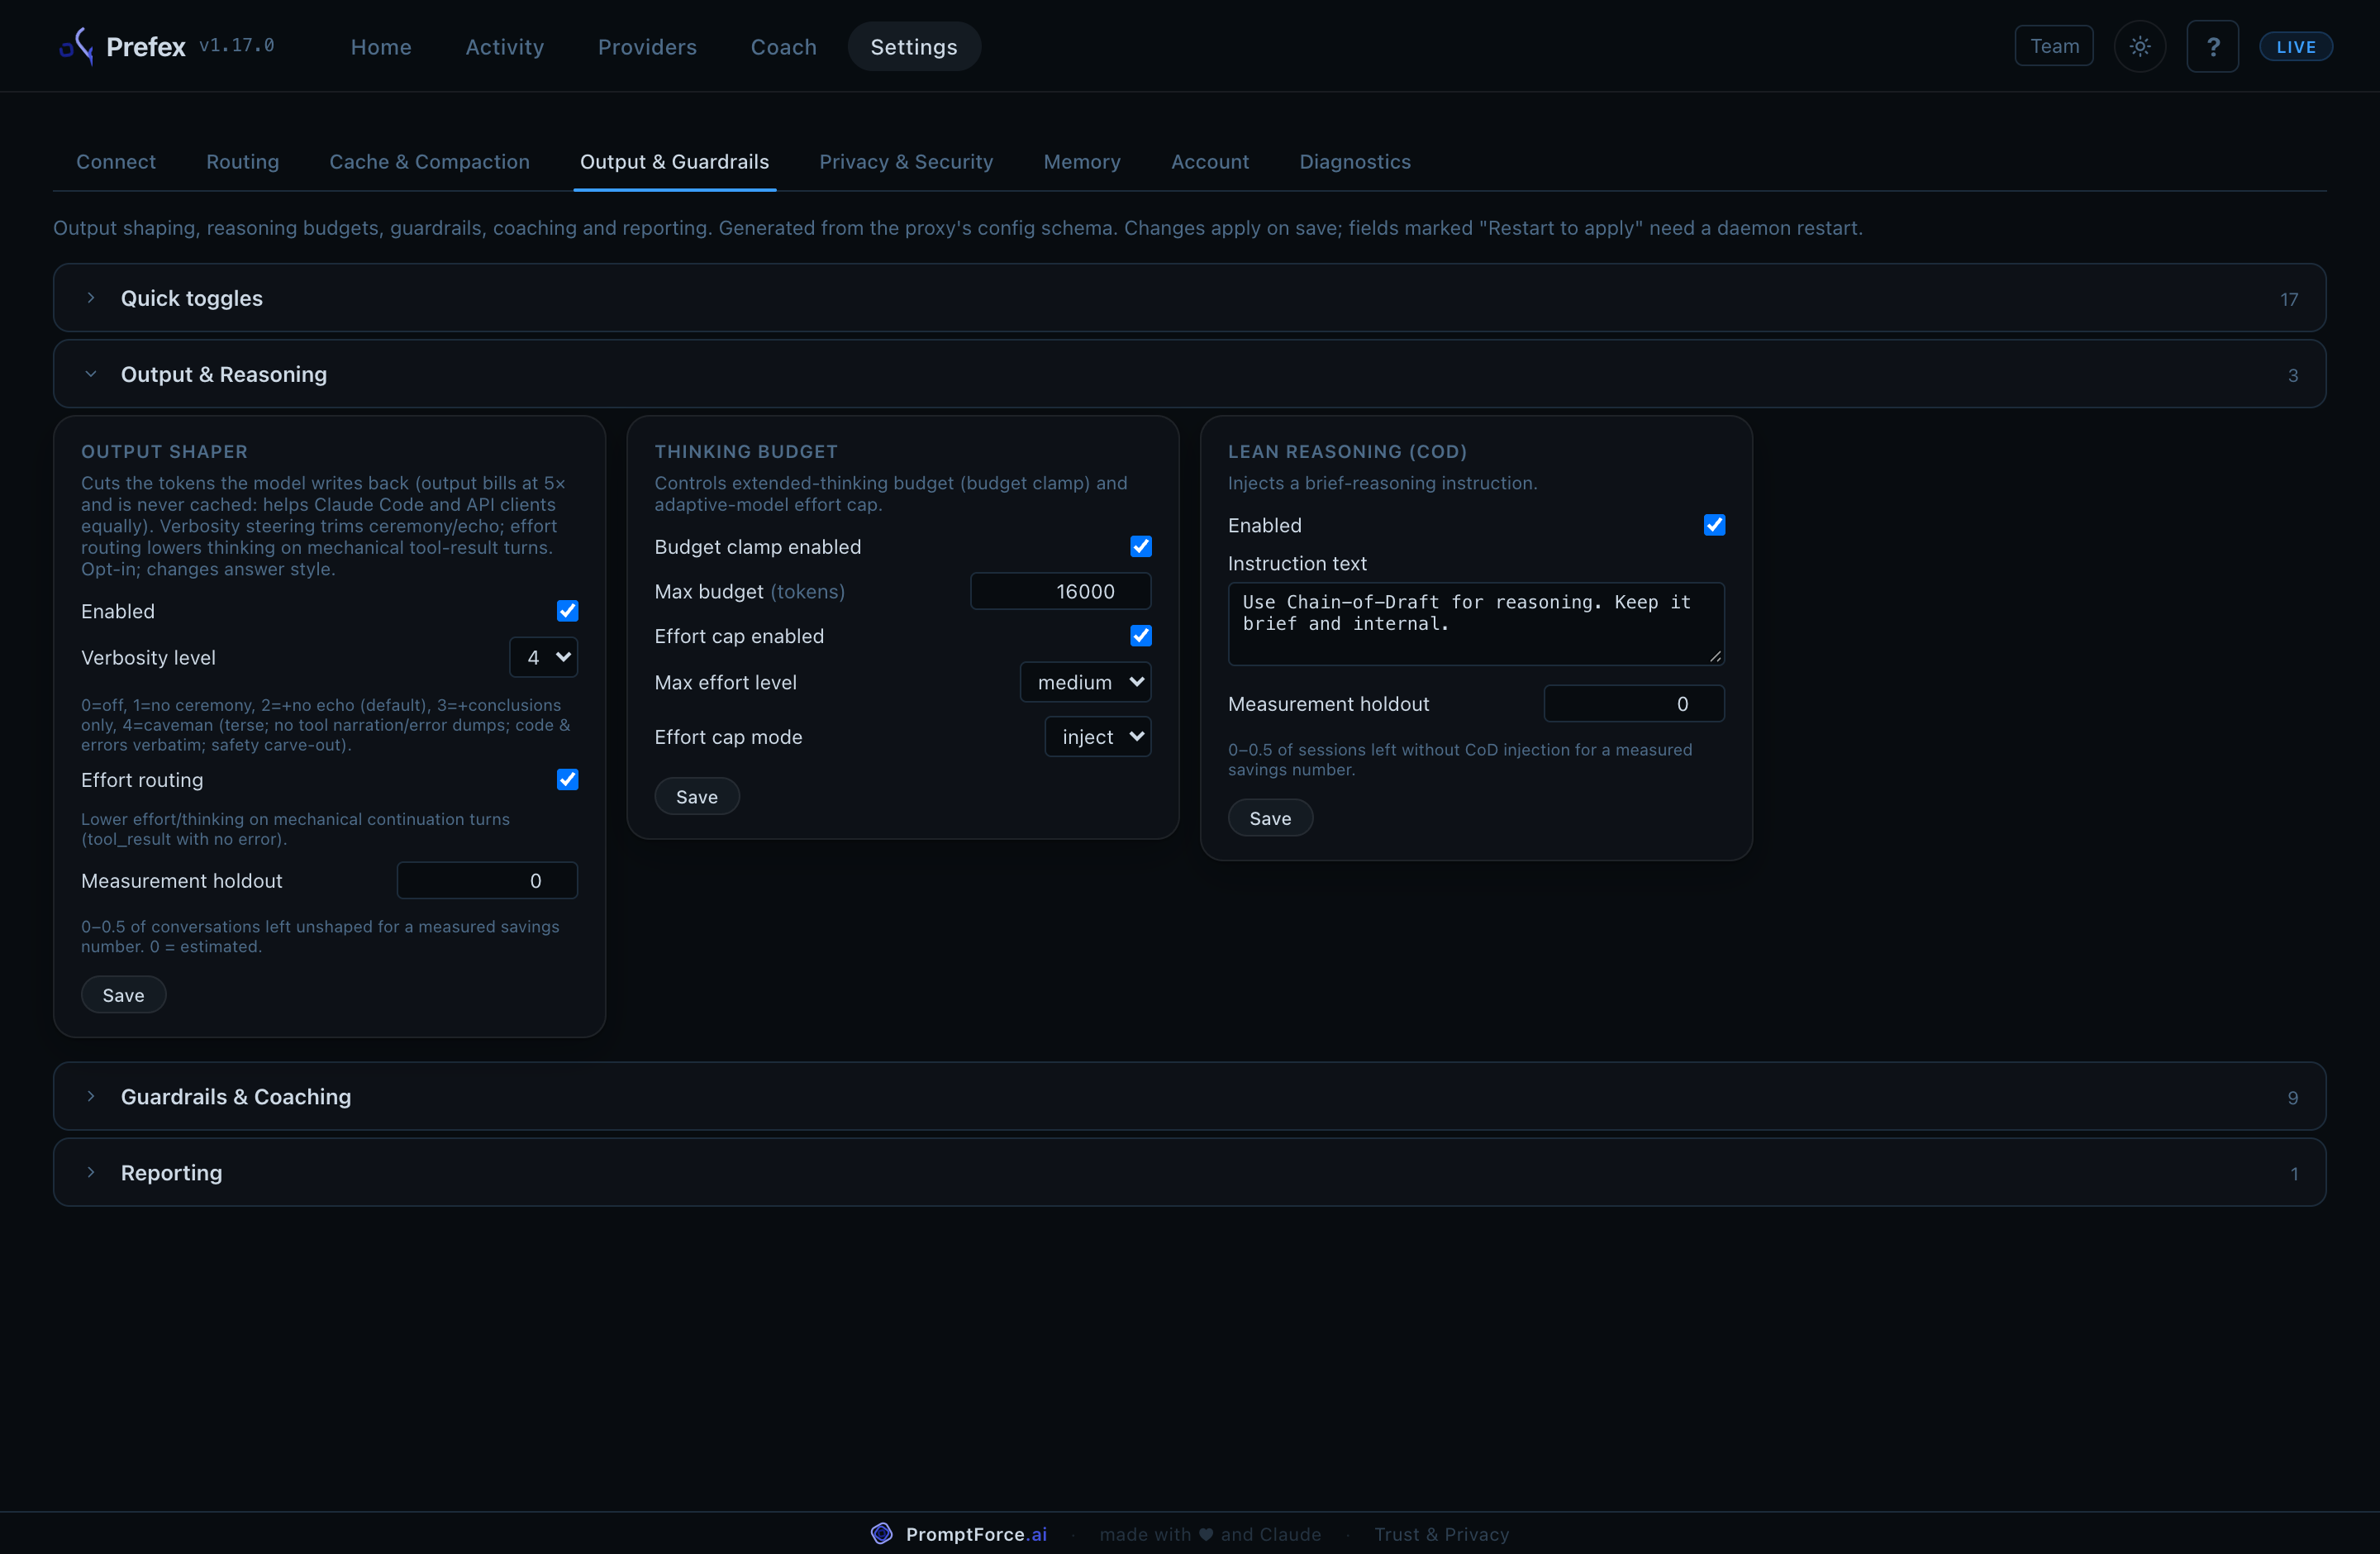
| Output Shaper | Trims model verbosity on mechanical turns — output tokens bill at 5× input and never cache. Measured on our own traffic, not vendor claims. | ~11% of output tokens (measured) | |
| Context Management | Context Recall | Saves conversation history locally; resume sessions without re-sending full context. Strictly per-project — one project's memory never surfaces in another. | 5–15% |
| Session Handover | At session end, distills a structured note (goal, progress, key files, blockers, next steps) and injects it once — cache-safely — into your next session in that project. | faster warm starts | |
| Write Gate | Prevents expensive turns from being written to session memory | varies | |
| Context Guard | Auto-prunes old messages when context approaches 75% fill | 5–15% | |
| Checkpoint | Summarizes and evicts old task brackets on long sessions | 30–50% on long sessions | |
| Guardrails | Loop Guard | Detects agents stuck repeating the same tool calls or errors. Advisory by default (logs); active mode stops the loop. | prevents runaway spend |
| Token Trap | Catches oversized requests before they are billed: prunes old turns first, then forwards with a warning, or in block mode stops the request with an explanation. | prevents runaway spend | |
| Spend Watcher | A background sentinel reads the live request stream and flags big cold cache writes, prefix flapping, rate limits, and spend spikes the moment they happen, to your status line and dashboard. | surfaces waste early | |
| Policy Gateway | An embedded OPA engine evaluates every tool call against policy — log-only advisory mode or hard enforcement. Also scans MCP tool descriptions at session start and logs suspicious ones to Activity → Guardrails. | governance, not savings | |
| Think / Effort Cap | Caps the thinking budget or effort level on routine turns so the model doesn't reason at length about a mechanical step | - | |
| Lean Reasoning | Instructs the model to reason briefly; saves 10–20% on explanation tokens | 10–20% |
These optimizations compound. Prompt caching alone saves 30–70%. Add routing and compression and the cost-reduction tier reaches 40–70% on its own. Context management extends how long sessions run within subscription limits. Guardrails prevent runaway spend on loops and expensive tasks.
Setting this up yourself means building a local proxy, parsing every request body, detecting cacheable prefixes, injecting the right headers, maintaining a session store, and building routing logic, all while ensuring zero downtime and fail-open behavior. If any of it breaks, your API calls fail. That's a full engineering project, not a weekend hack.
Claude Code Max & Pro: Extended Session Runtime
If you're on Claude Code Max or Pro (subscription plans with fixed token limits), Prefex solves a different but equally critical problem: extending how long your sessions can run. Prefex works by sitting between Claude Code and Anthropic — your subscription credentials are used normally through Claude Code. Prefex doesn't grant API access beyond what your plan includes.
The subscription token limit problem
- Max 5, ~88,000 tokens per 5-hour window
- Max 20, ~220,000 tokens per 5-hour window
- Weekly limits, cap resets weekly (exact number undisclosed)
- Everything counts, Claude Code + claude.ai + Claude Desktop all share the same pool
The problem: your CLAUDE.md and project context get counted fresh on every request. If your system prompt is 100K tokens and you make 50 requests in a session, you've already used 5M tokens just on repeated context, well over your 5-hour window before you've written a line of code.
How Prefex extends your runway
By caching your system prompt and routing simple requests to cheaper inference paths, Prefex dramatically reduces tokens billed against your subscription quota:
| Scenario | Without Prefex | With Prefex | Extra requests |
|---|---|---|---|
| 50 requests (100K system prompt) | 5M tokens (blocked after 10 min) | 0.6M tokens (full day possible) | +40 extra requests |
| 200 requests (large CLAUDE.md) | 20M tokens (blocked after 2 min) | 1.8M tokens (full session) | +180 extra requests |
Real example from a beta tester: After adding Prefex, this developer could sustain an 8-hour coding session without hitting the weekly limit. Previously, they hit the ceiling after 2 hours. Same subscription tier, same work, just smarter token usage.
Why subscription users benefit most
Unlike API plan users (who pay per token), subscription users have a fixed budget that runs out. Cost optimization isn't about saving money, it's about staying productive within your allocated window.
- Prompt cache, Anthropic's cache saves 90% on re-sent context, but expires after 5 minutes idle and resets if you switch models. Prefex keeps it perpetually warm.
- Routing, simple tasks (formatting, refactoring, questions) route to cheaper inference paths automatically
- Session management, redundant conversation history is trimmed, reducing bloat over long sessions
Combined, these optimizations typically extend session runtime by 300-500% before hitting limits.
You don't care about saving money, your fee is fixed. You care about how much work you can get done before hitting your quota. Prefex takes you from 1-2 hour sessions to full 8-hour days.
Real Before/After Numbers
These are from actual Claude Code sessions running through Prefex, measured via the local dashboard:
Example: 8-hour coding day
| Metric | Without Prefex | With Prefex |
|---|---|---|
| Requests | 180 | 180 |
| Input tokens | 2.4M | 2.4M (sent) / 0.8M (billed) |
| Cache hit rate | 0% | 88% |
| Routed to cheaper model | 0% | 34% |
| Total cost | $8.40 | $2.90 |
| Saved | $5.50 (65%) |
Monthly impact
| Developer profile | Monthly without | Monthly with | Annual savings |
|---|---|---|---|
| Part-time (3 days/week) | $60 | $21 | ~$470/year |
| Full-time solo dev | $200 | $70 | ~$1,560/year |
| Team of 5 | $1,000 | $350 | ~$7,800/year |
How Prefex Works
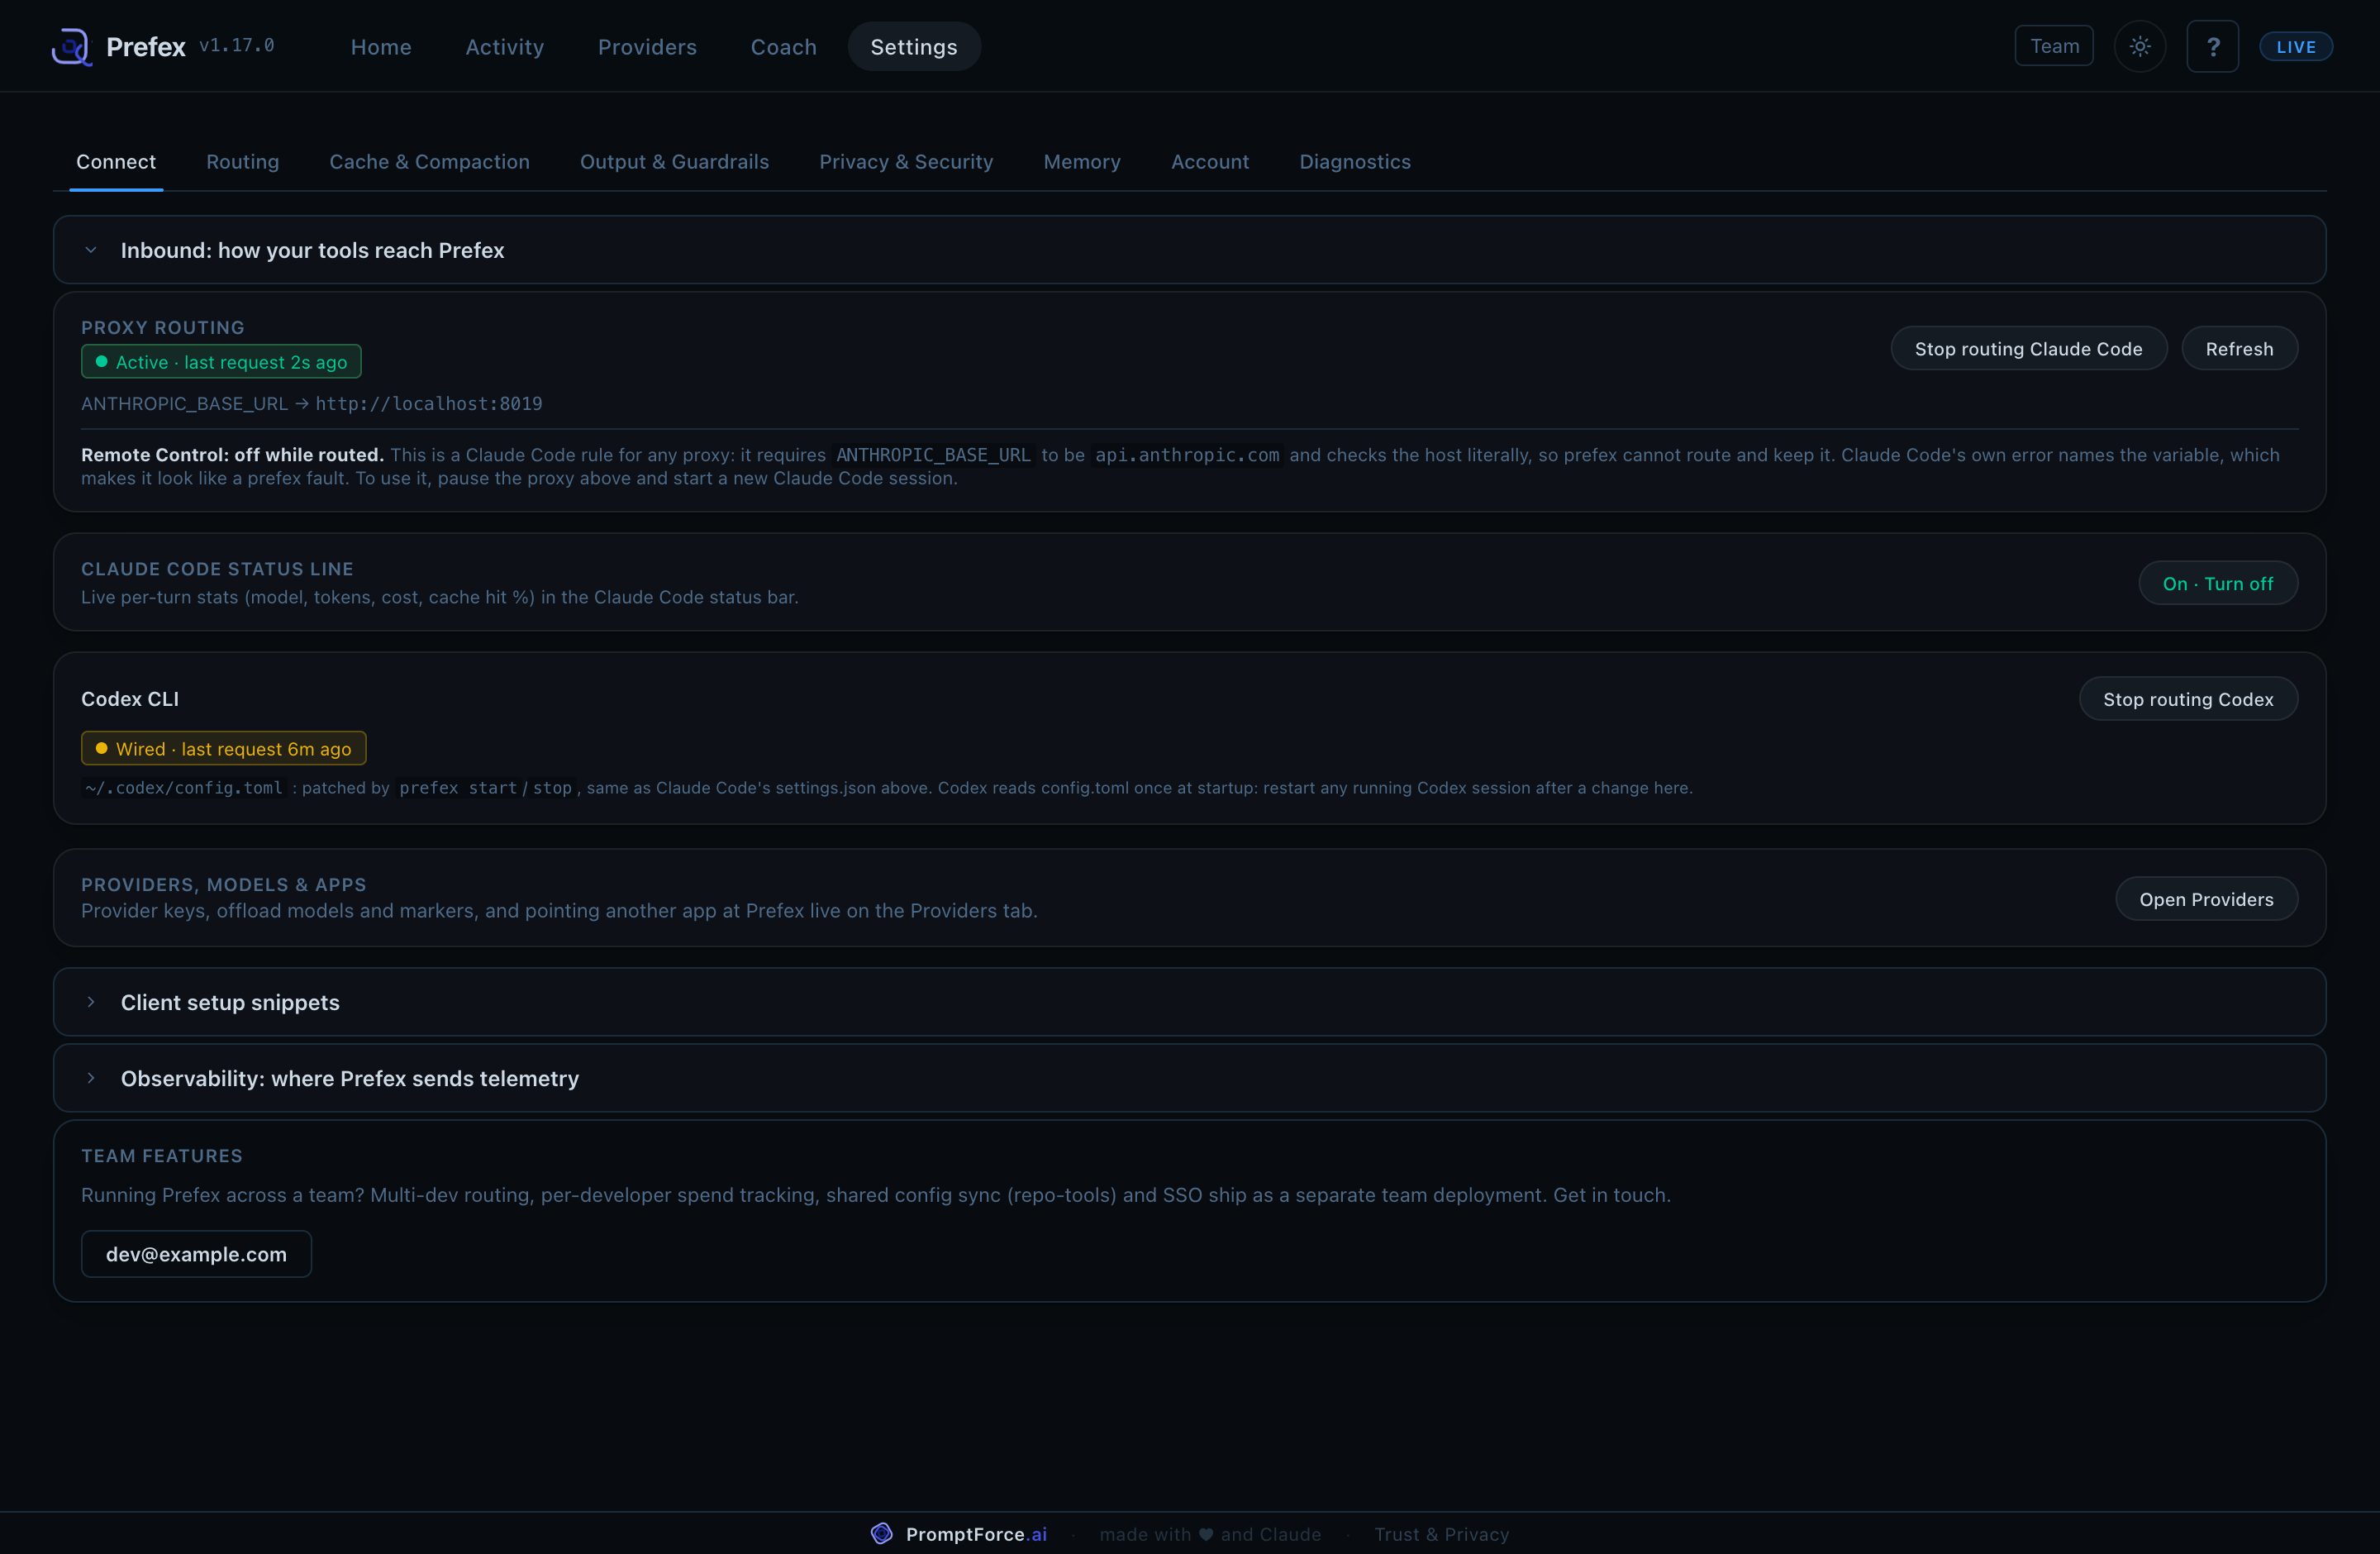
Prefex is a single binary that runs on your machine. You change one setting in Claude Code to route through it. From that point on, every API request passes through Prefex before reaching Anthropic.
// ~/.claude/settings.json, the only change
{ "env": { "ANTHROPIC_BASE_URL": "http://localhost:8019" } }
Prefex inspects each request, applies optimizations, and forwards it to Anthropic. If anything goes wrong internally, the request goes straight to Anthropic unchanged, your work is never interrupted.
What happens on each request
- Detects the client type (Claude Code, API, agent) and applies the right feature set
- Loads any prior session context from the local store
- Injects
cache_controlheaders so Anthropic caches the prefix at 1h TTL (vs the default 5-minute idle expiry); routes requests to preserve the cached model rather than invalidate it on a model switch, 0.1× cost on a hit - Evaluates complexity and routes simple requests to the cheaper model, validating the request body stays valid on that model before switching
- Optionally sets the reasoning effort level from the same complexity score (effort routing), on the same model
- Compresses verbose CLI output before it reaches the model
- Forwards the request to Anthropic and streams the response back
- Logs tokens, cost, savings, and routing decision to local SQLite
Prefex's own processing adds roughly 10–65 ms per request depending on body size, small next to the upstream round-trip. Your workflow doesn't change. Prompts and credentials go only to the provider that serves the request. The one other thing prefex sends is a daily licence check: a salted machine hash and the savings meter reading, never prompts, keys or email.
The dashboard
Open localhost:8019/dashboard to see real-time savings, per-project costs, cache hit rates, and routing decisions. It's the fastest way to understand where your money goes and confirm optimizations are working.
Install: the App or One Command
PromptForce is one app with Prefex and ReadyBase inside. On a Mac or a Windows PC, install the app. On Linux, or if you live in a terminal, use the command line. Both end in the same place: Prefex running on your own machine with Claude Code pointed at it. The free licence lasts until Prefex has saved you $500 beyond native prompt caching; no card. See Licence for what happens after.
Download PromptForce App → Pick Apple silicon, Intel Mac or Windows. On Linux, the same page gives you the install command.
The PromptForce app (macOS, Windows beta)
Install. On a Mac, open the DMG and drag PromptForce to Applications. It is signed and notarized, and Prefex ships inside it, so nothing else downloads. On Windows, unzip it and run PromptForce. It is signed by DayTwoAI LLC, so Smart App Control allows it; SmartScreen may still warn on a new release until that release builds reputation.
Setup. It first asks How will you use PromptForce?: Just me, Join my team, or Set up a team. Before anything changes, What setup will change shows you the list.
- Welcome. Shows the coding apps it found (Claude Code, Codex). Subscriptions pass straight through. If you use a separate API key, add it here and it is encrypted into a local vault.
- Style. How hard Prefex should work: Careful, Balanced (recommended) or Maximum.
- This Mac. A hardware check suggests a local model that can run routine work on your machine (needs Ollama). You can also add ReadyBase here.
When it finishes, Claude Code is pointed at Prefex. If setup stops partway, nothing is left half-configured.
Privacy is not asked during setup. It lives in Preferences › Privacy, with two switches: Keep a private record on this Mac (on), which keeps your prompts in Prefex's local database so Coach and your reports can use them and never sends them to PromptForce, and Scrub secrets (off), which masks secrets before a request leaves your machine.
Menu bar. The icon shows whether Prefex is working, stopped or paused, plus today's spend, context, cache and Saved: what Prefex saved beyond what prompt caching alone would have. From the menu you can stop or start Prefex, pause it for 15 minutes, an hour or until you resume, open the dashboard, pick what the menu bar title shows, and set up providers. Click the icon for a panel with a Prefex tab and a ReadyBase tab (AI-readiness score, scan a folder). The savings card filters Today, 7d, 30d or All. On a team hub the menu shows Team hub · N members · M active this week; on a member machine it shows Team: <name> · via hub.
Preferences. Providers (models you can use, saved keys, Jev), Behaviour, Privacy, Licence and More, where Remove Prefex and ReadyBase shows what it would do before it does it. Quitting the app leaves Prefex running, so your AI keeps working. The app checks for Prefex updates every hour and shortly after your Mac wakes, and Check for Updates in the menu checks now; if your agents are busy when you click update, it installs once they go idle.
Just you, or a team
Opt-in. Every provider key you add puts that provider's free models in one pool, and side jobs your agents hand off run there instead of your plan. Each provider is labelled by what it says it does with your data, and you choose per project how far your code may go. Set it up in Set Up Providers › Free pool.
Make this computer the hub your teammates' agents go through: run setup and choose Set up a team, then invite people from Set Up Providers › More. The menu bar shows how many members you have and who is active. Free until your team saves $500.
Click the invite link your admin sent, or paste it at setup's Join my team. Your agents go through the team's hub with your own sign-in; if the hub stops answering, PromptForce goes direct until it is back, where the team allows it.
Running a team: see the team guide.
Command line (Linux, Debian, Ubuntu, or any Mac)
One command installs Prefex, starts it and connects Claude Code, then installs ReadyBase. Run only the first line if you want Prefex alone.
curl -fsSL https://promptforce.ai/install.sh | bash &&
curl -fsSL https://promptforce.ai/rb-install.sh | bash
Prefer to read the script first? It shows what it will change, then downloads the binary, verifies its checksum, starts the daemon and connects Claude Code:
curl -fsSL https://promptforce.ai/install.sh -o install.sh && less install.sh
bash install.sh
Connect more clients later with prefex install --clients claude_code,codex. Every command is in the CLI Reference.
First look
The app opens the dashboard from the menu bar. From a terminal:
open http://localhost:8019/dashboard
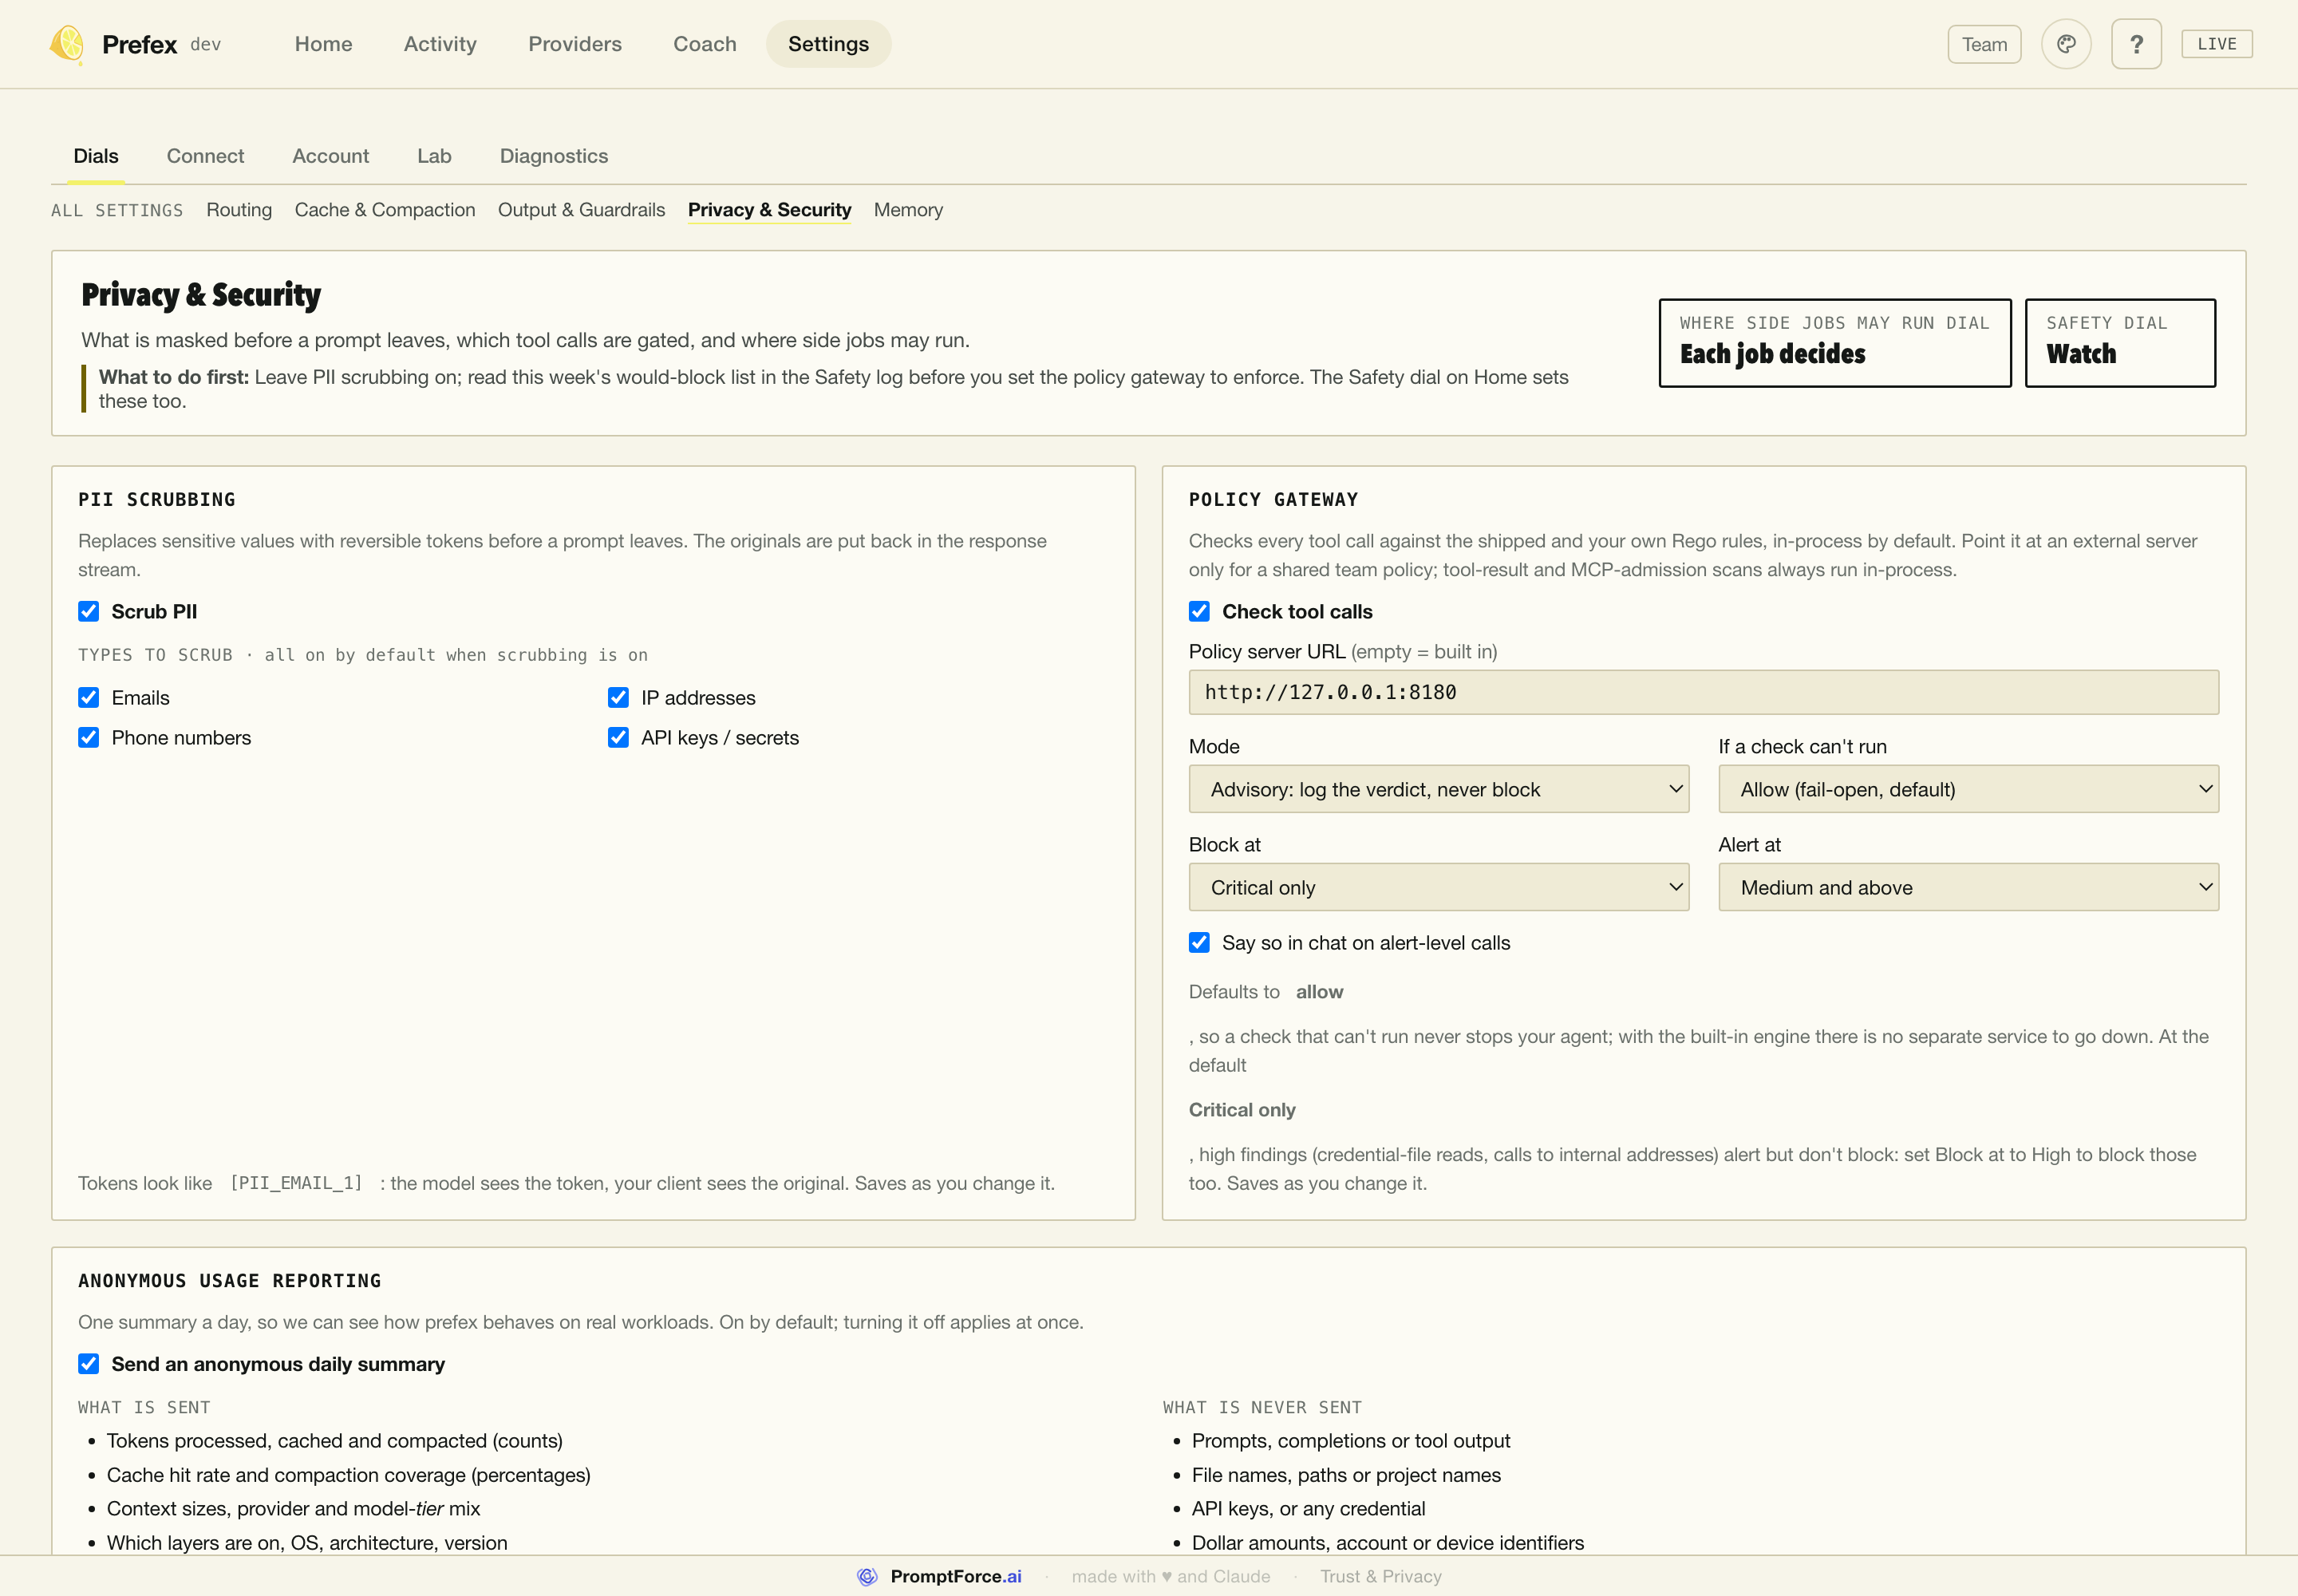
- Privacy: runs on localhost, prompts never logged off your machine. The anonymous daily usage summary is on by default; turn it off in Settings → Privacy & Security. Full details →
- Reversible: in the app, Preferences → More. From a terminal,
prefex uninstall(or the uninstall script) restores your original settings. See Uninstall.
Make a few Claude Code requests and check your dashboard. You'll see cache hits climbing and cost per request dropping within minutes. The community leaderboard shows what other developers are saving.
Beyond Claude Code: One Daemon for Every Tool
Prefex isn't Claude-Code-only. prefex wrap launches any AI coding tool through the same shared daemon — one SQLite ledger, one dashboard, per-tool attribution — without touching your global settings. Only that session routes through the proxy.
prefex wrap codex -- exec "fix the failing test"   # Codex, this session only
prefex wrap aider                                   # any CLI tool: env injected into the child
prefex wrap opencode                                # also: claude, copilot
prefex wrap cursor                                  # GUI tools: prints the Settings values to paste
Codex talks the OpenAI Responses API — prefex exposes /v1/responses and forwards transparently, so wrap works without translation hacks. The dashboard's By tool panel breaks spend out per channel: claude_code, codex, cursor, aider, opencode, copilot. Zed and other GUI apps can be pointed at the same base URL by hand.
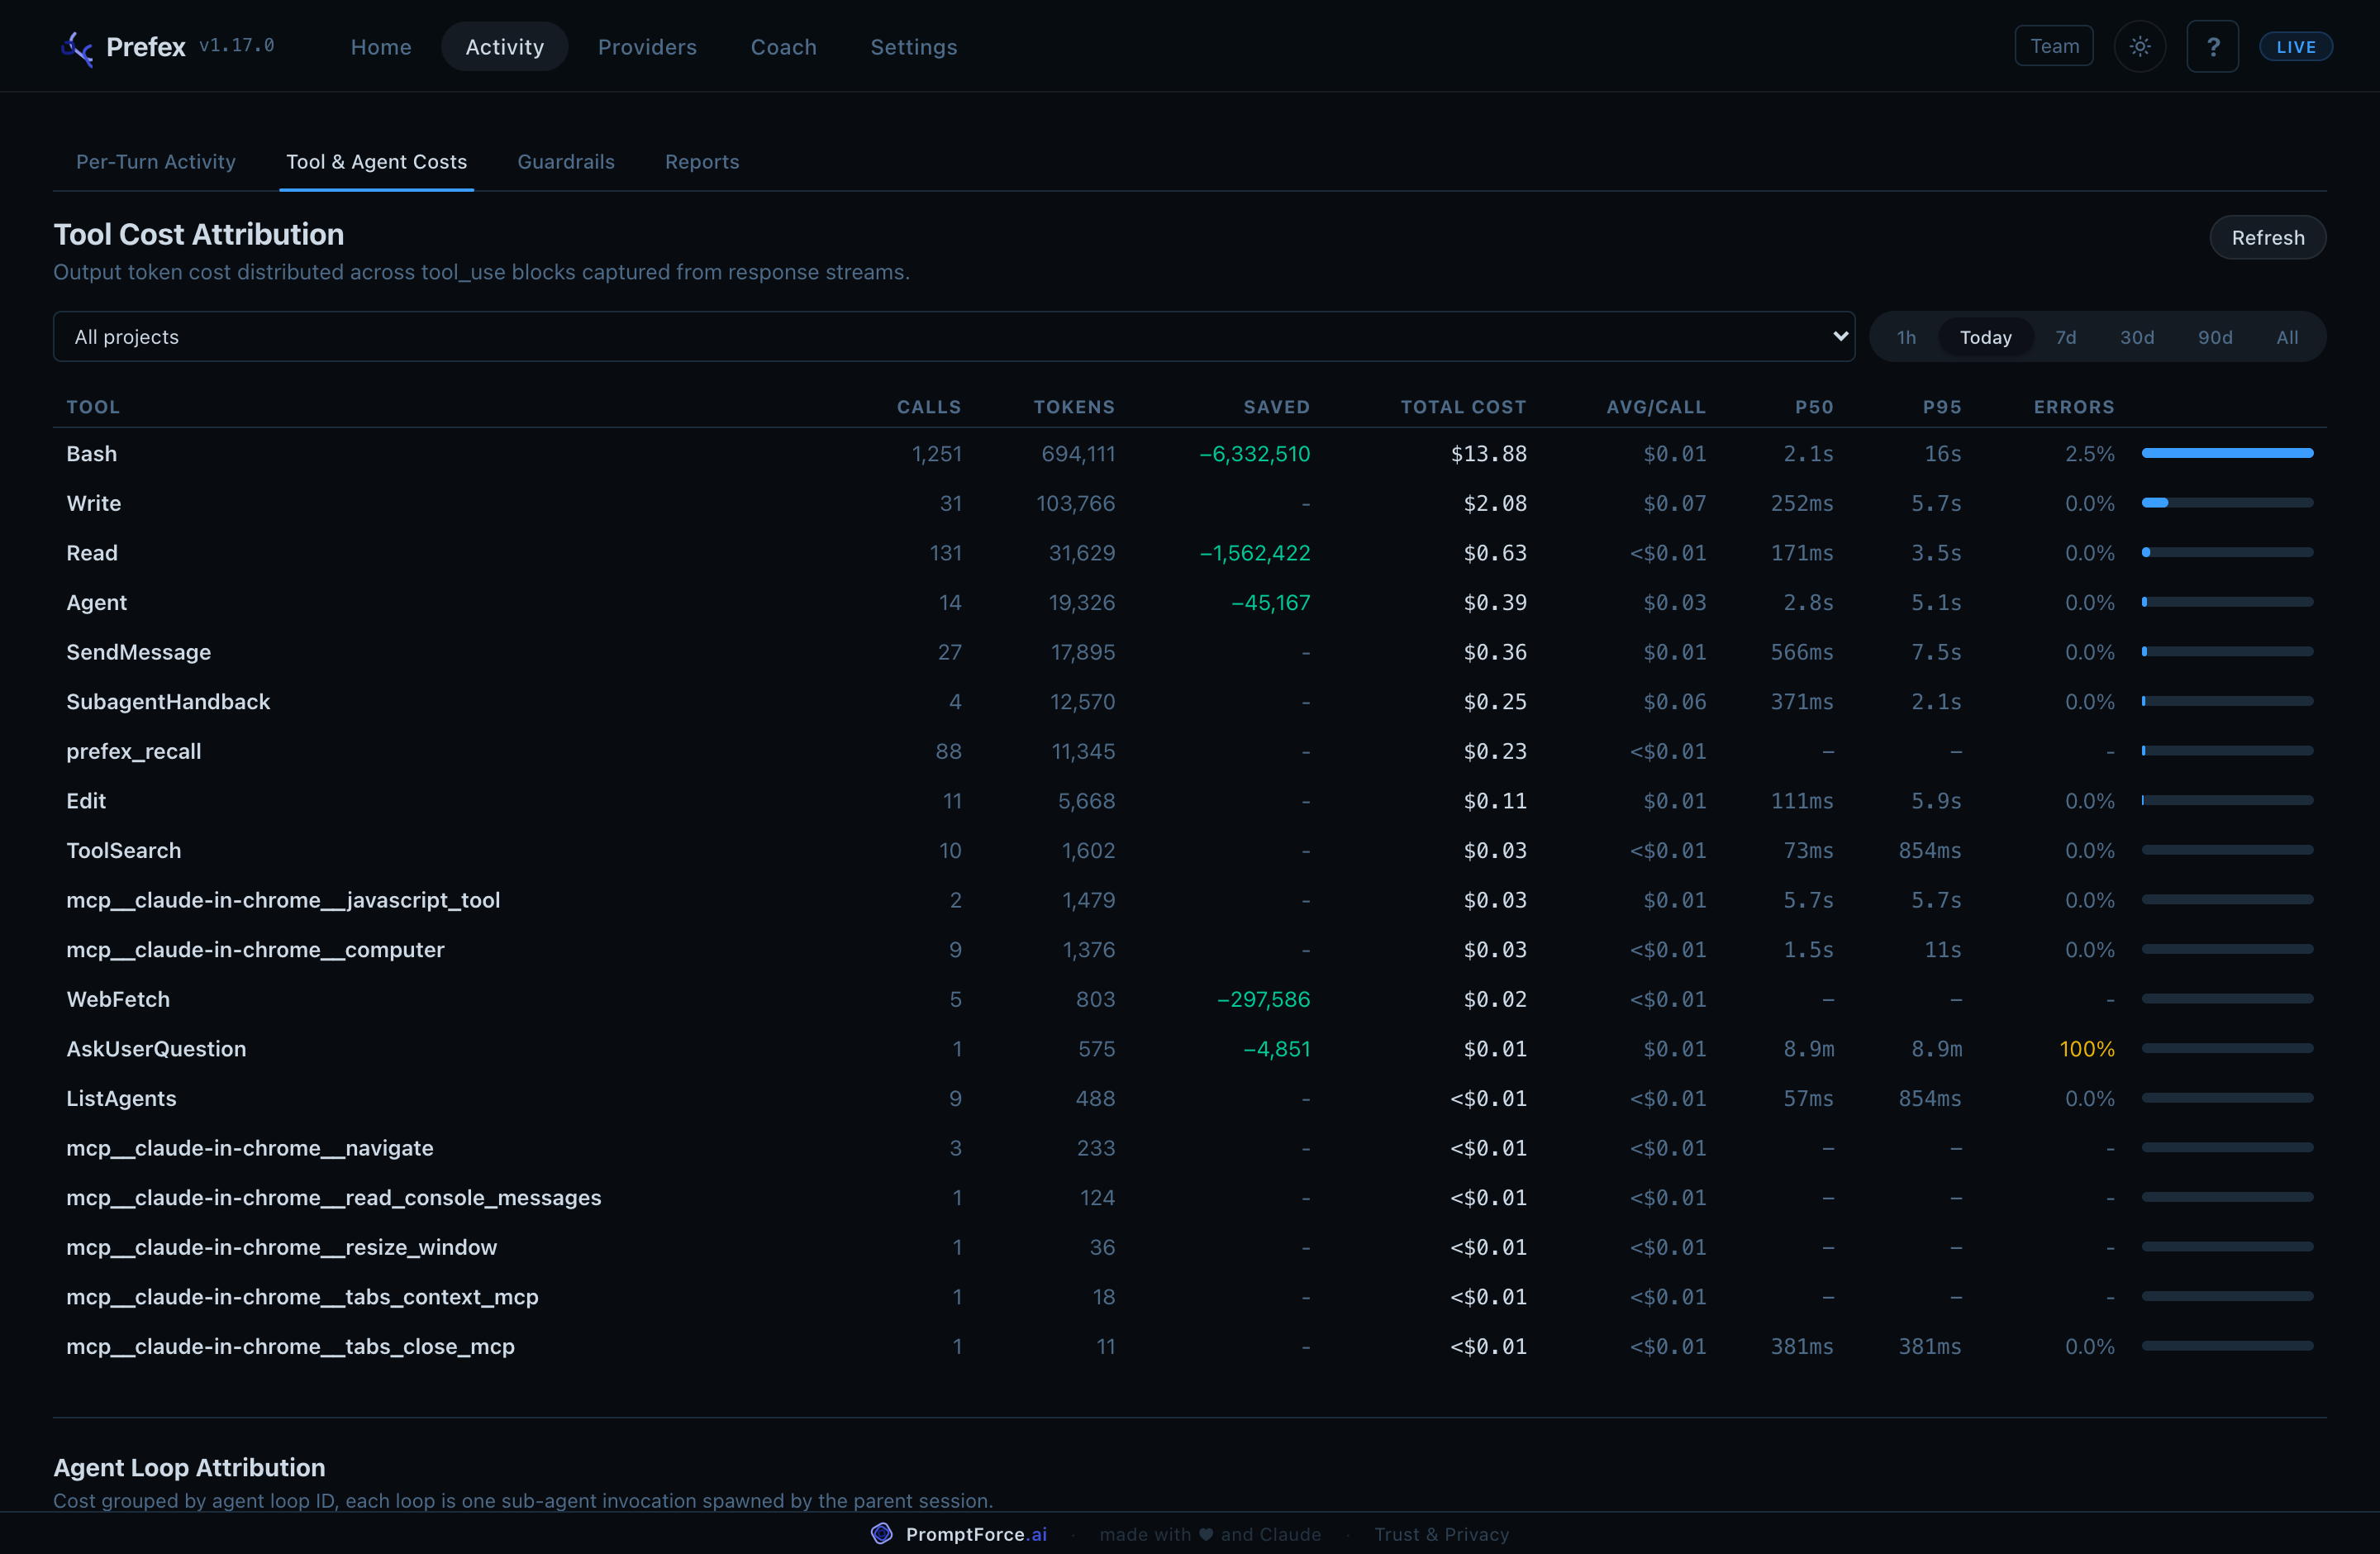
Rates for ~3,000 models across providers resolve at log time from an embedded pricing snapshot (refreshed each release, or on demand with prefex pricing refresh). A model the table doesn't know is flagged unpriced in the dashboard — never silently priced at a guess.
Policy Gateway: Tool-Call Governance
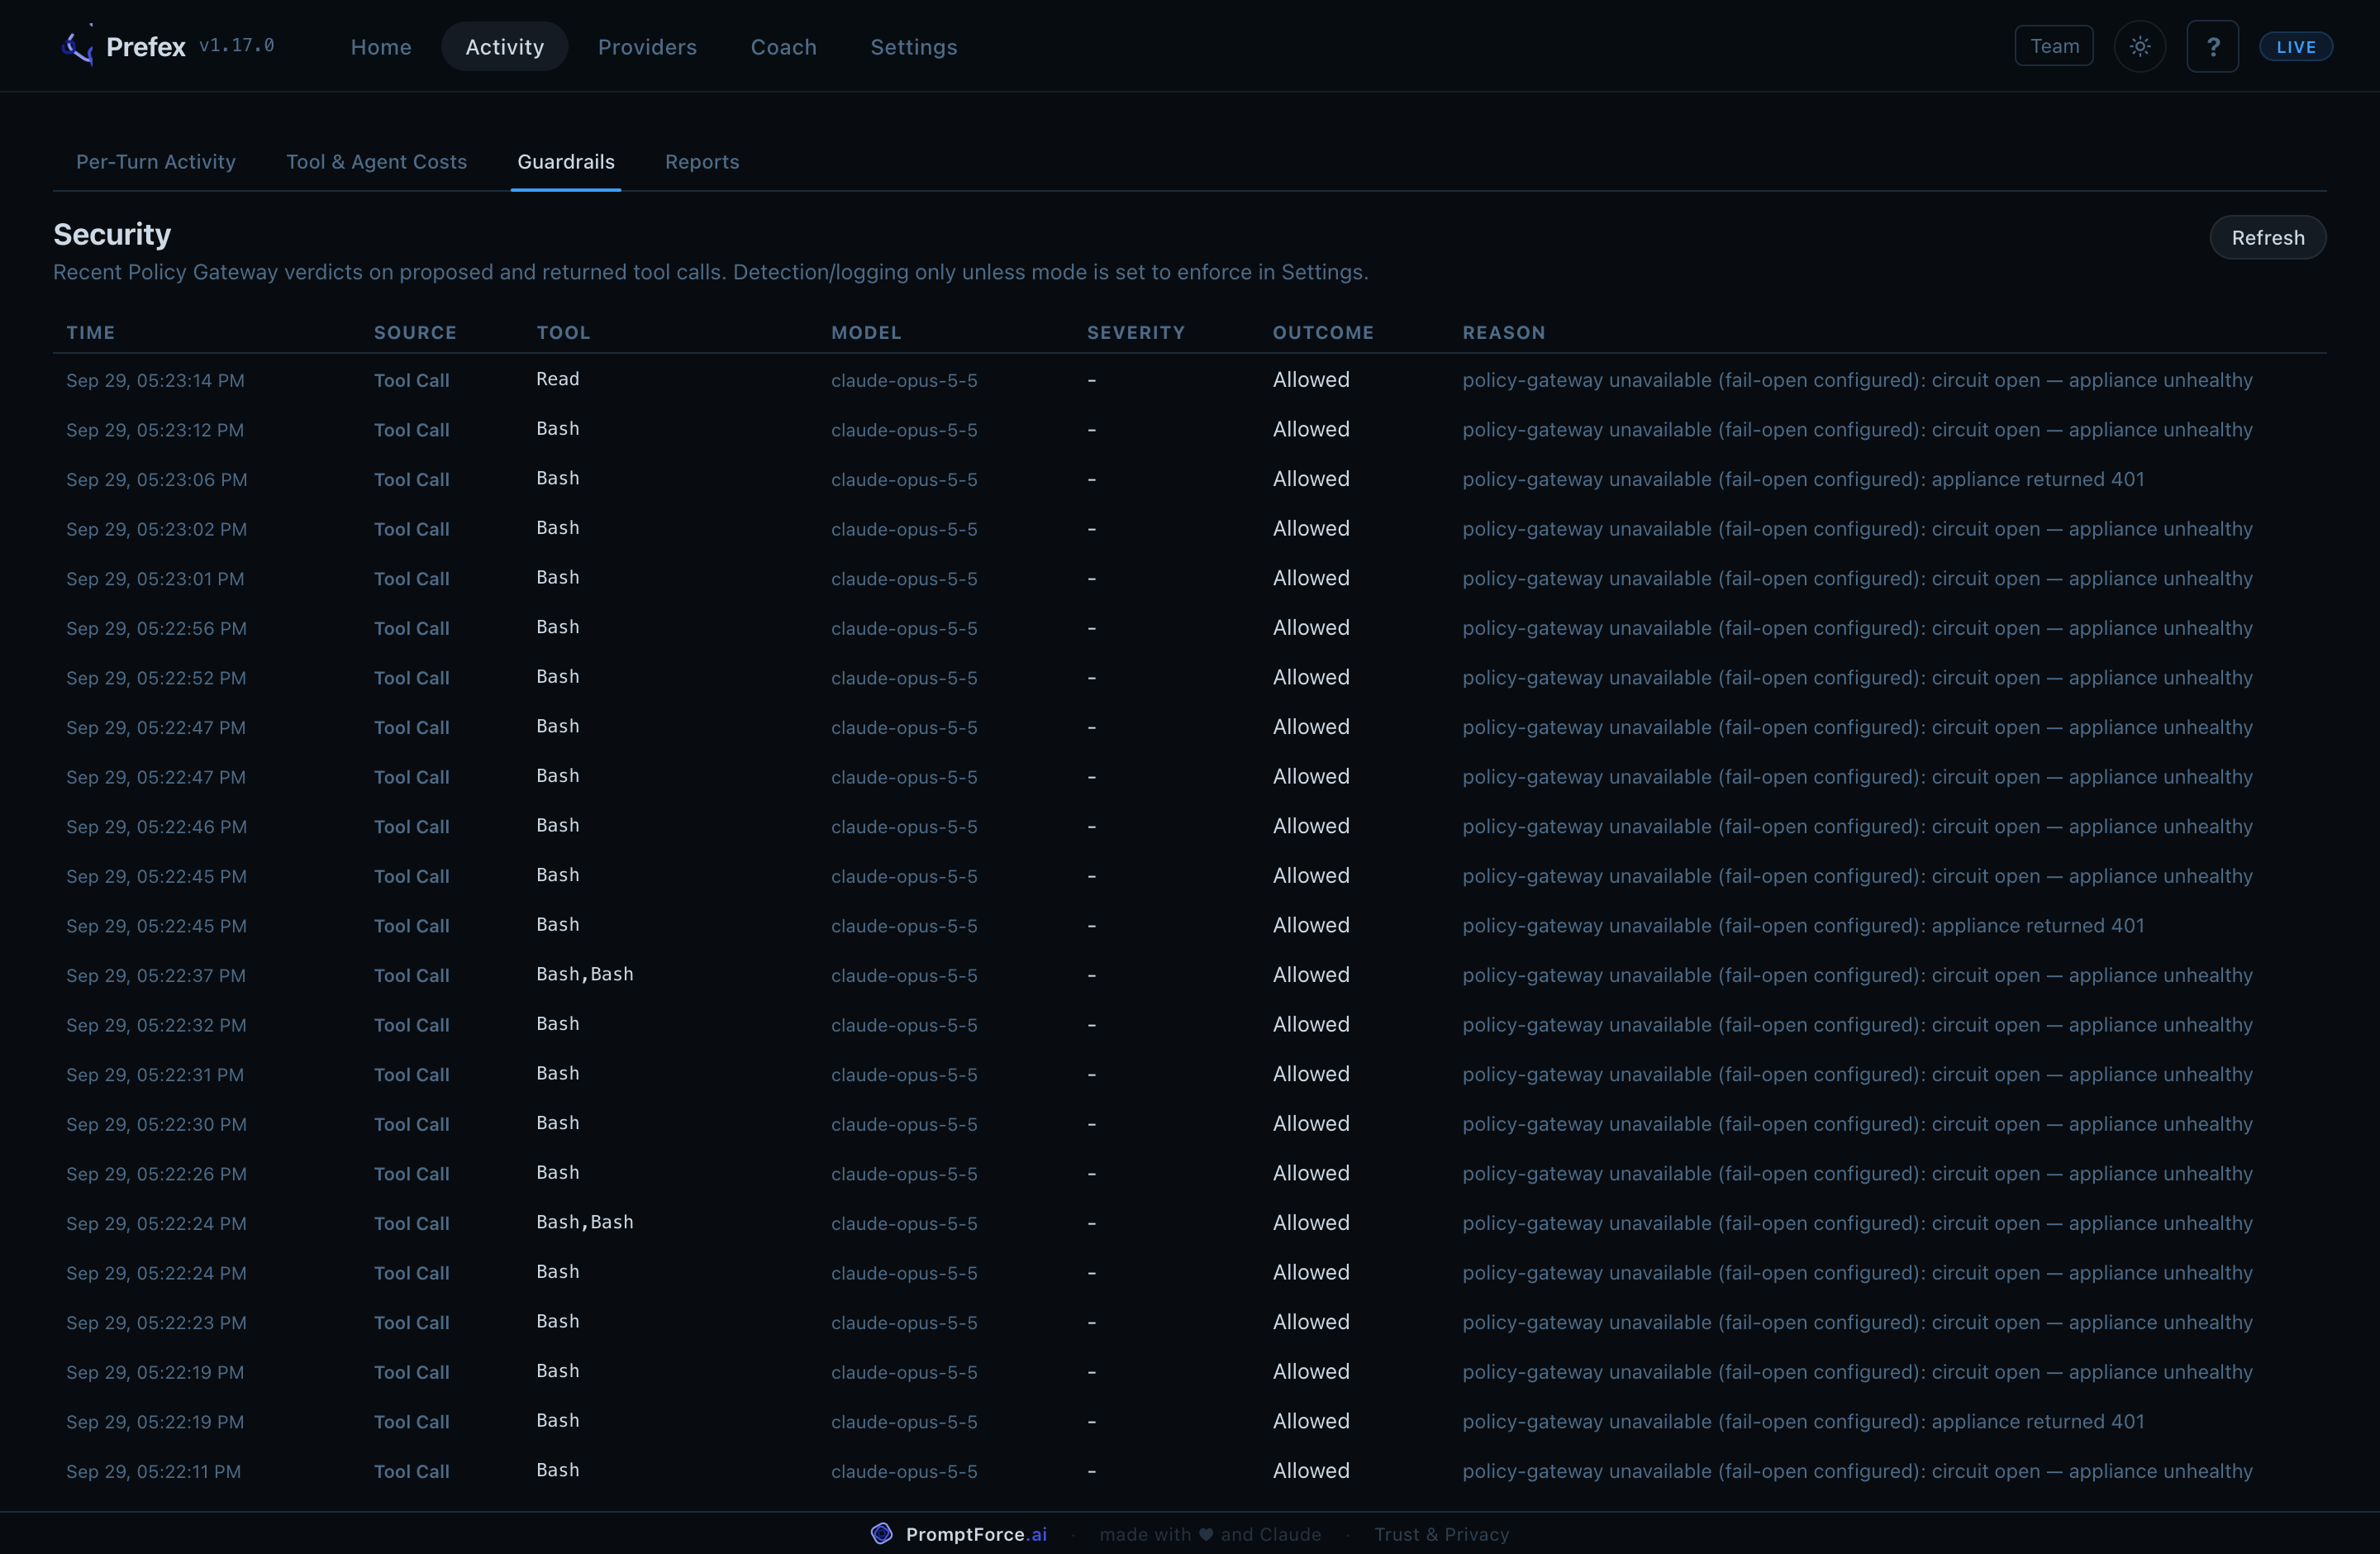
Agents don't just spend tokens — they run tools. The policy gateway puts an embedded OPA engine (the same policy language platform teams already use) on the wire: every tool call the model makes is evaluated against your policies before it executes.
- Advisory mode logs verdicts to Activity → Guardrails — see what would be blocked before you enforce anything.
- Enforce mode blocks tool calls that violate policy, fail-open on engine errors so governance never breaks a request.
- MCP admission scan: tool descriptions offered to the model at session start are scanned for prompt-injection patterns; suspicious ones are logged to the same Guardrails view (detection and audit — this scan flags, it doesn't block).
- Safe policy loading: a broken user-authored
.regonever takes the gateway down — prefex falls back to the shipped policy bundle and surfaces the compile errors on the dashboard.
prefex:
  policy_gateway:
    enabled: true
    mode: advisory        # advisory | enforce
    block_threshold: critical  # enforce blocks only at/above this severity
    # url: ""             # empty = in-process OPA; or an external OPA server
    on_unavailable: allow # fail-open
Policies live on your machine, evaluate in-process, and nothing leaves localhost — same trust model as the rest of prefex.
Secrets Vault (API Keys for Agents)
When you run AI agents that call external APIs, GitHub, Slack, your own services, you have two options: embed real credentials in the prompt, or use the secrets vault.
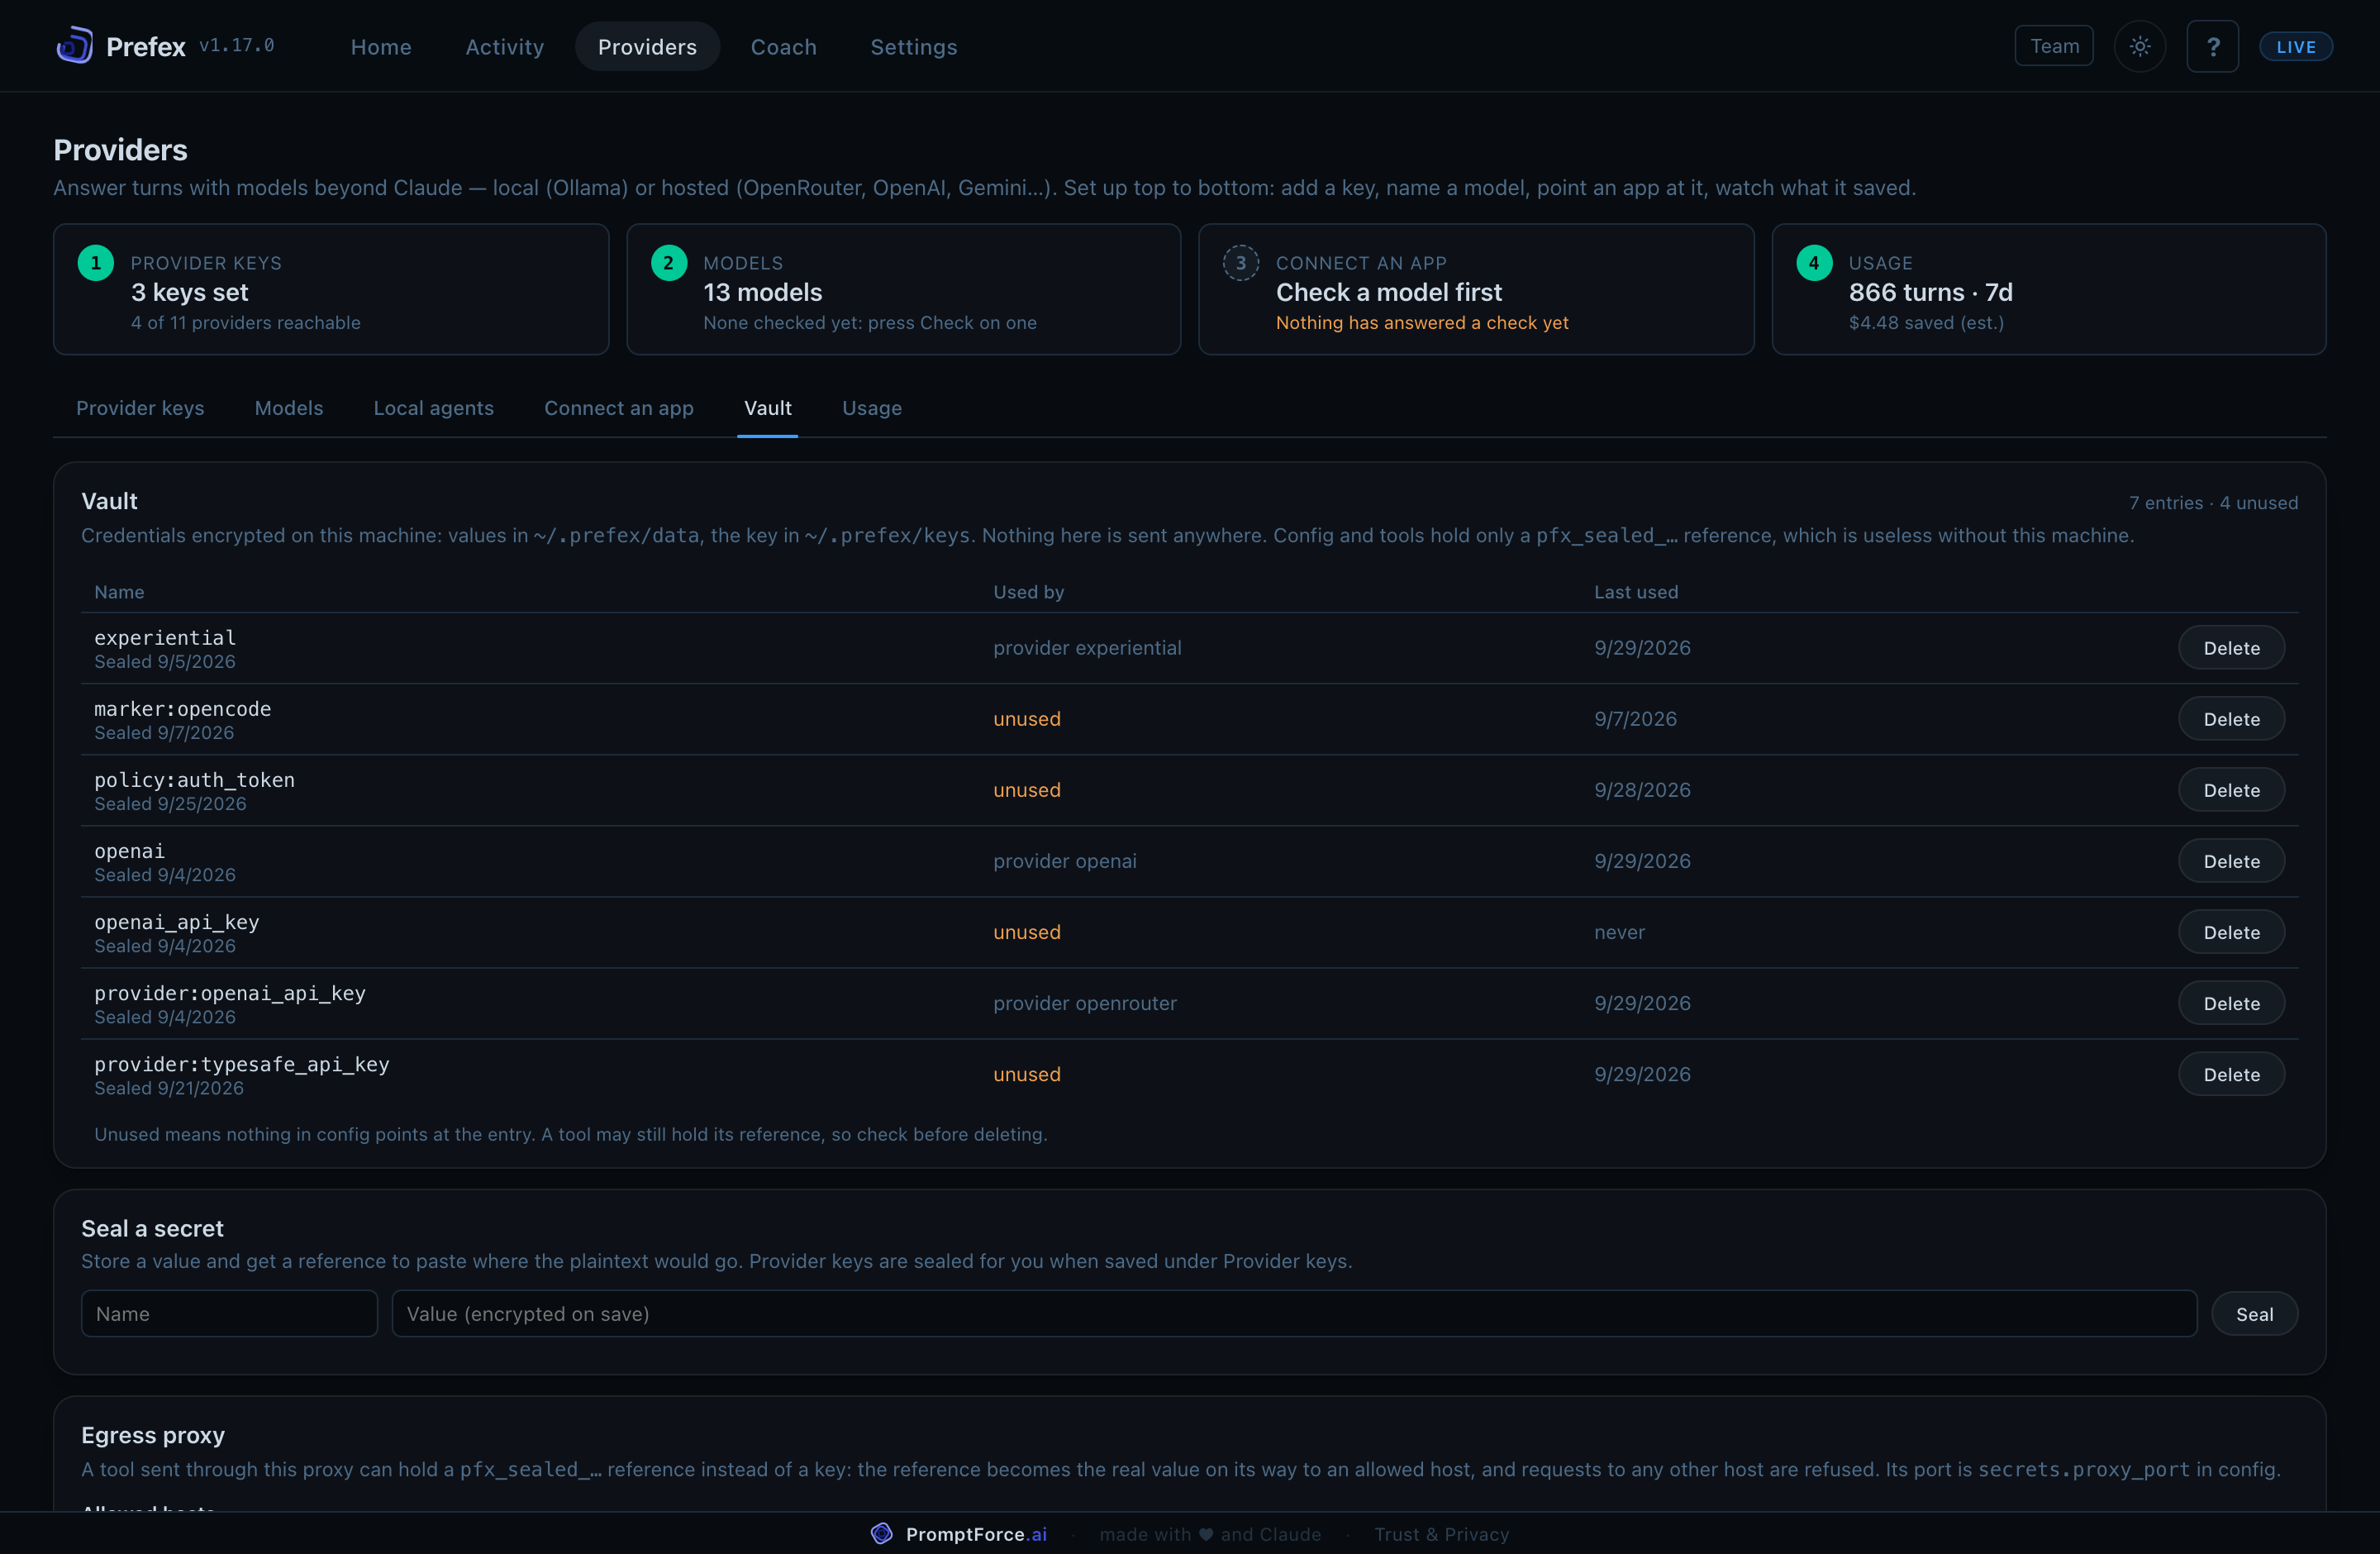
The secrets vault encrypts your credentials and issues a sealed token (pfx_sealed_…). You put the token in your agent's prompt. The proxy intercepts outgoing HTTPS requests, substitutes the token with the real value, and forwards the request, the agent and any logs only ever see the token, not the credential.
How it works
- Enable secrets in config:
secrets.enabled: true - Store a credential:
prefex secret add github-token ghp_xxxx…, prints a sealed token - In your Claude Code session or CLAUDE.md:
Use auth header: pfx_sealed_a3f2… - Point your agent at the secrets proxy:
export HTTPS_PROXY=http://127.0.0.1:8020 - Outgoing requests with the token in headers or body get the real credential automatically
The MITM proxy
The secrets proxy runs on port 8020 (configurable). It terminates TLS using a local CA certificate you generate and trust once. Only hosts you add to the allowlist are intercepted, everything else is blocked to prevent accidental interception.
Out of the box, only api.anthropic.com and api.openai.com are in the allowlist. Add other hosts in the dashboard under Providers → Vault, or in secrets.allowlist in config.
CLI commands
prefex secret add <name> <value>     # encrypt and store; prints sealed token
prefex secret list                    # list secrets (name + token, no plaintext)
prefex secret remove <name>           # delete a secret
prefex secret show-ca                 # print the CA cert (PEM)
prefex secret install-ca              # install CA in system trust store (with confirmation)
Config
prefex:
  secrets:
    enabled: true
    proxy_port: 8020          # default
    key_dir: ~/.prefex/keys   # vault.key stored here, 0600
    allowlist:
      - api.anthropic.com
      - api.openai.com
      - api.github.com
The vault key at ~/.prefex/keys/vault.key is the encryption root. Back it up and keep it private, losing it means losing access to all stored secrets. The MITM CA cert should only be installed on machines you control; it grants the proxy the ability to intercept HTTPS for allowlisted hosts.
Dashboard Tour
The dashboard at localhost:8019/dashboard has five tabs. Press ? in it for the built-in guide.
- Home: your usage, and a card per feature layer with its switches.
- Activity: Per-Turn Activity (projects, sessions, turns), Tool & Agent Costs, Guardrails and Reports.
- Providers: provider keys, models and offload markers, local agents, Connect an app, the Vault and per-provider usage.
- Coach: tips from your own traffic, Setup Health, Context Audit, Prompt Doctor and Memories.
- Settings: Connect, Routing, Cache & Compaction, Output & Guardrails, Privacy & Security, Memory, Account and Diagnostics.
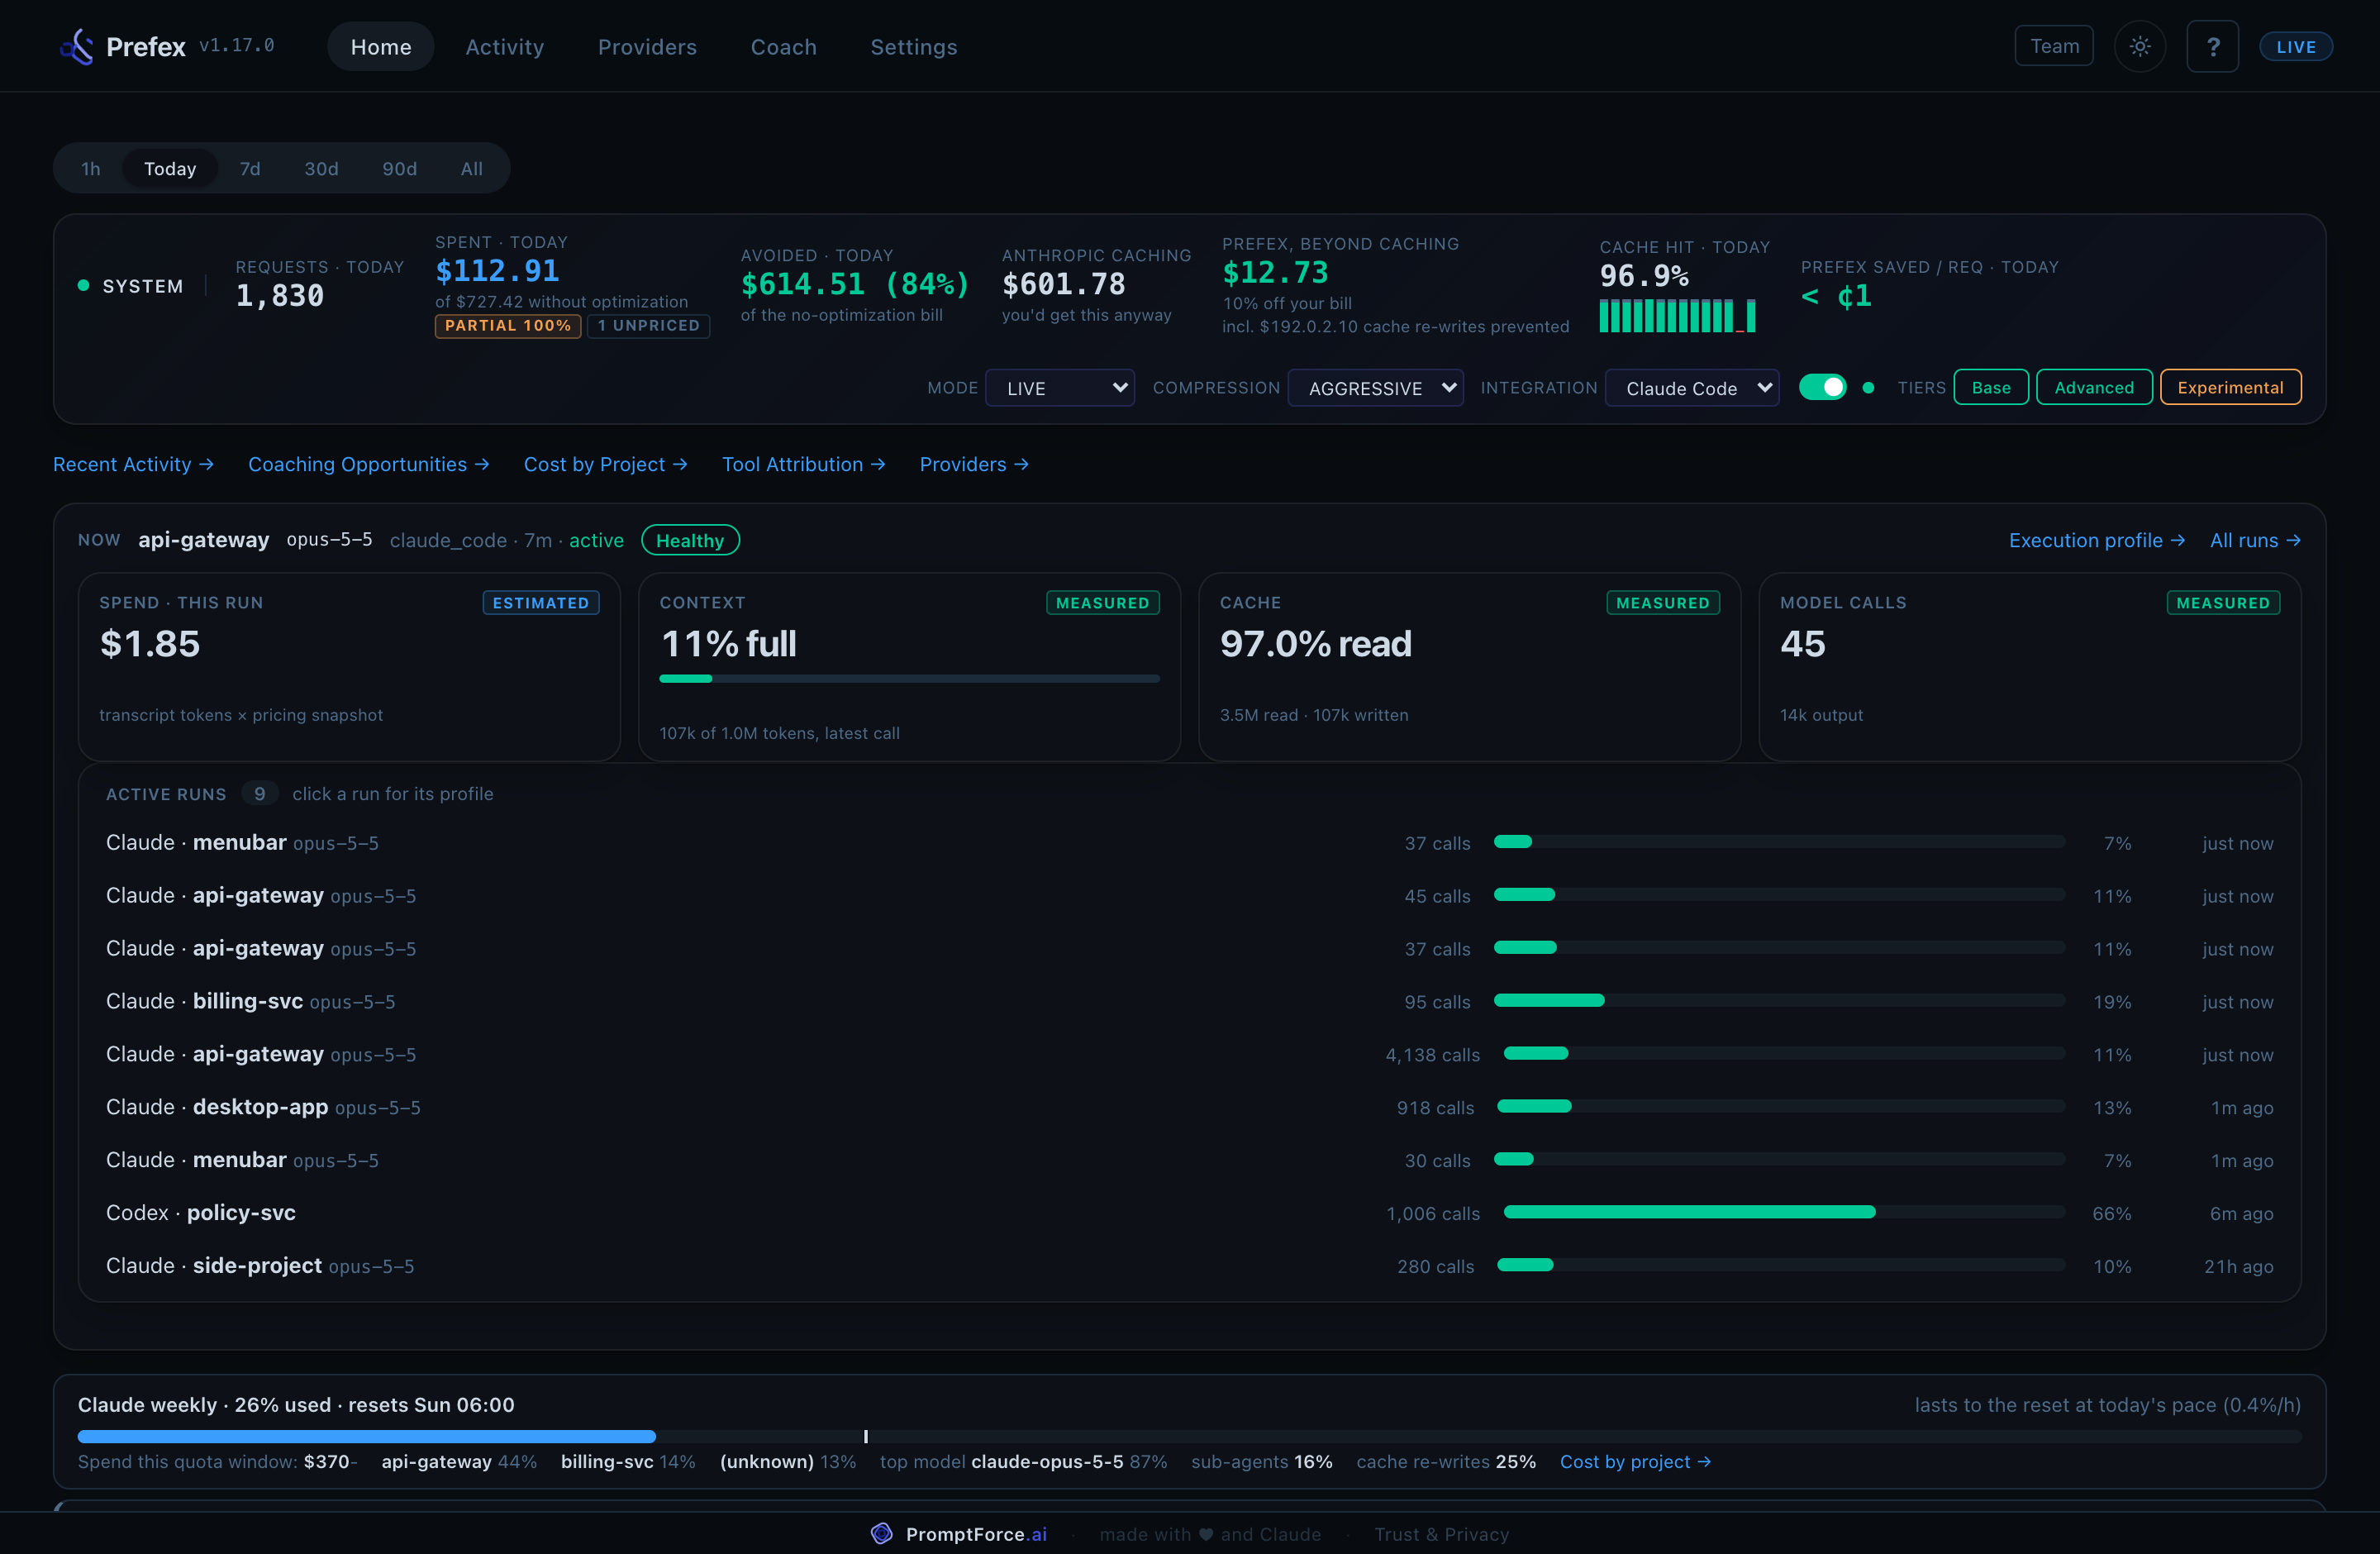
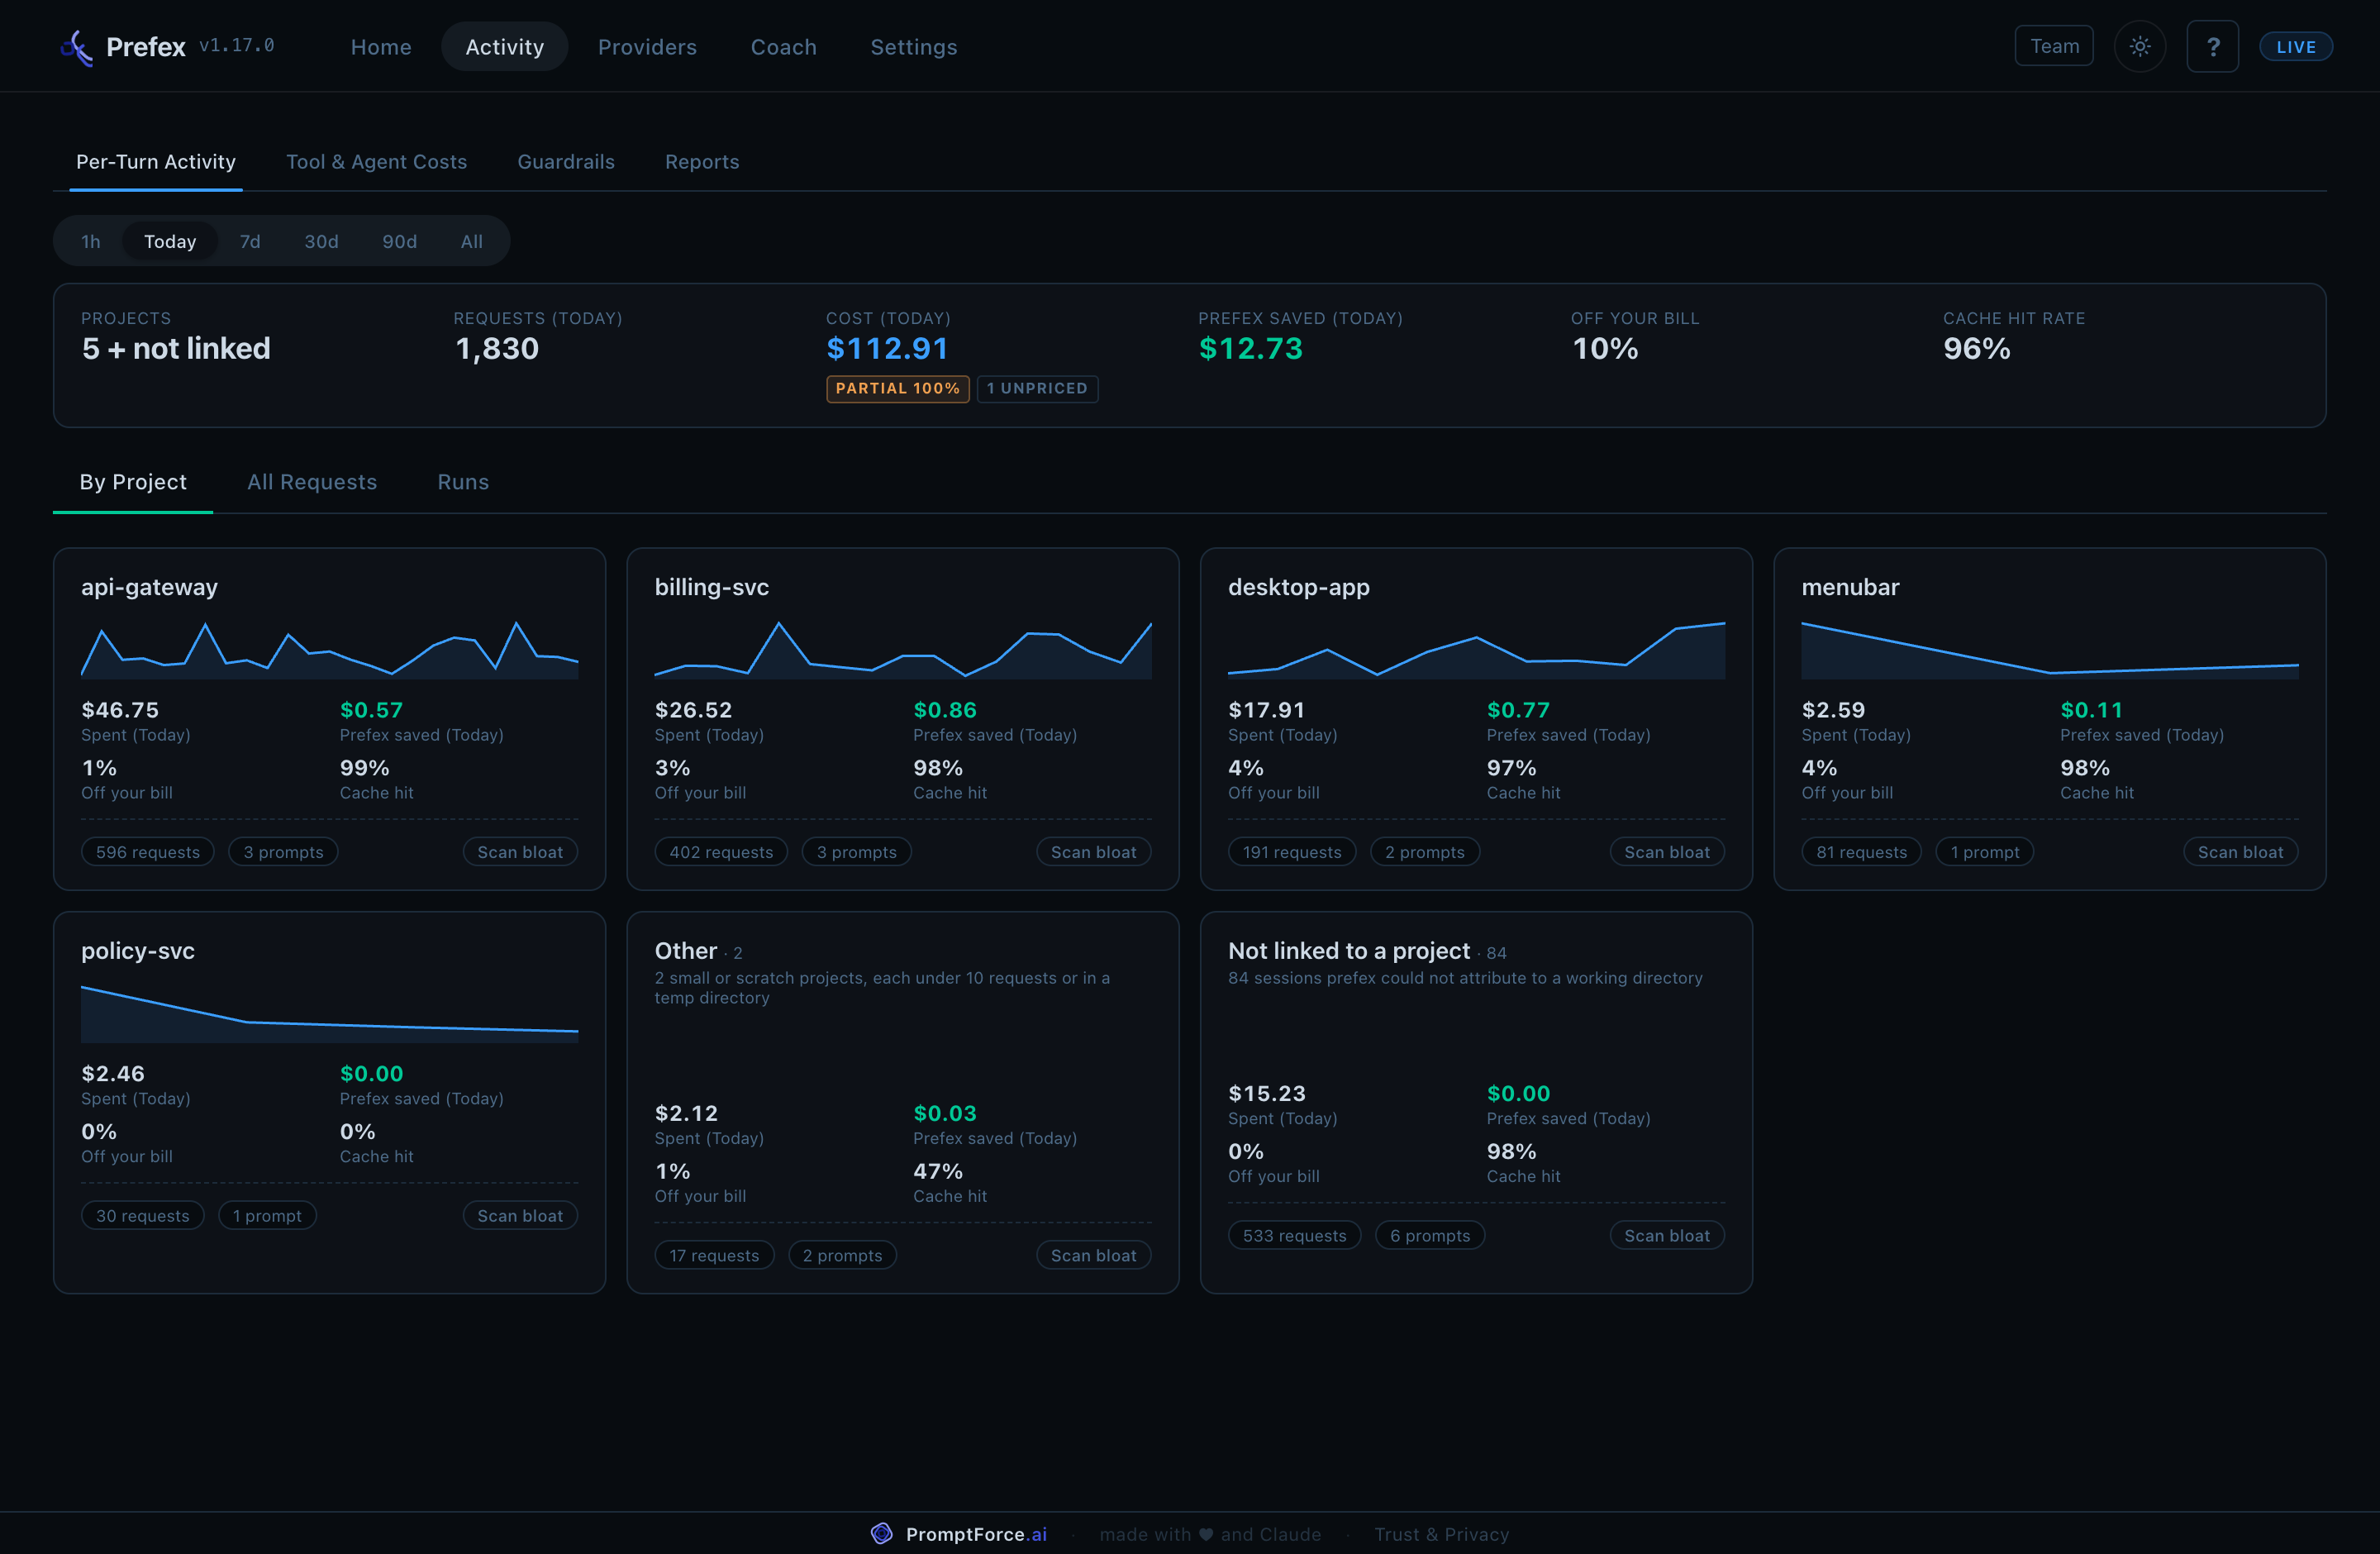
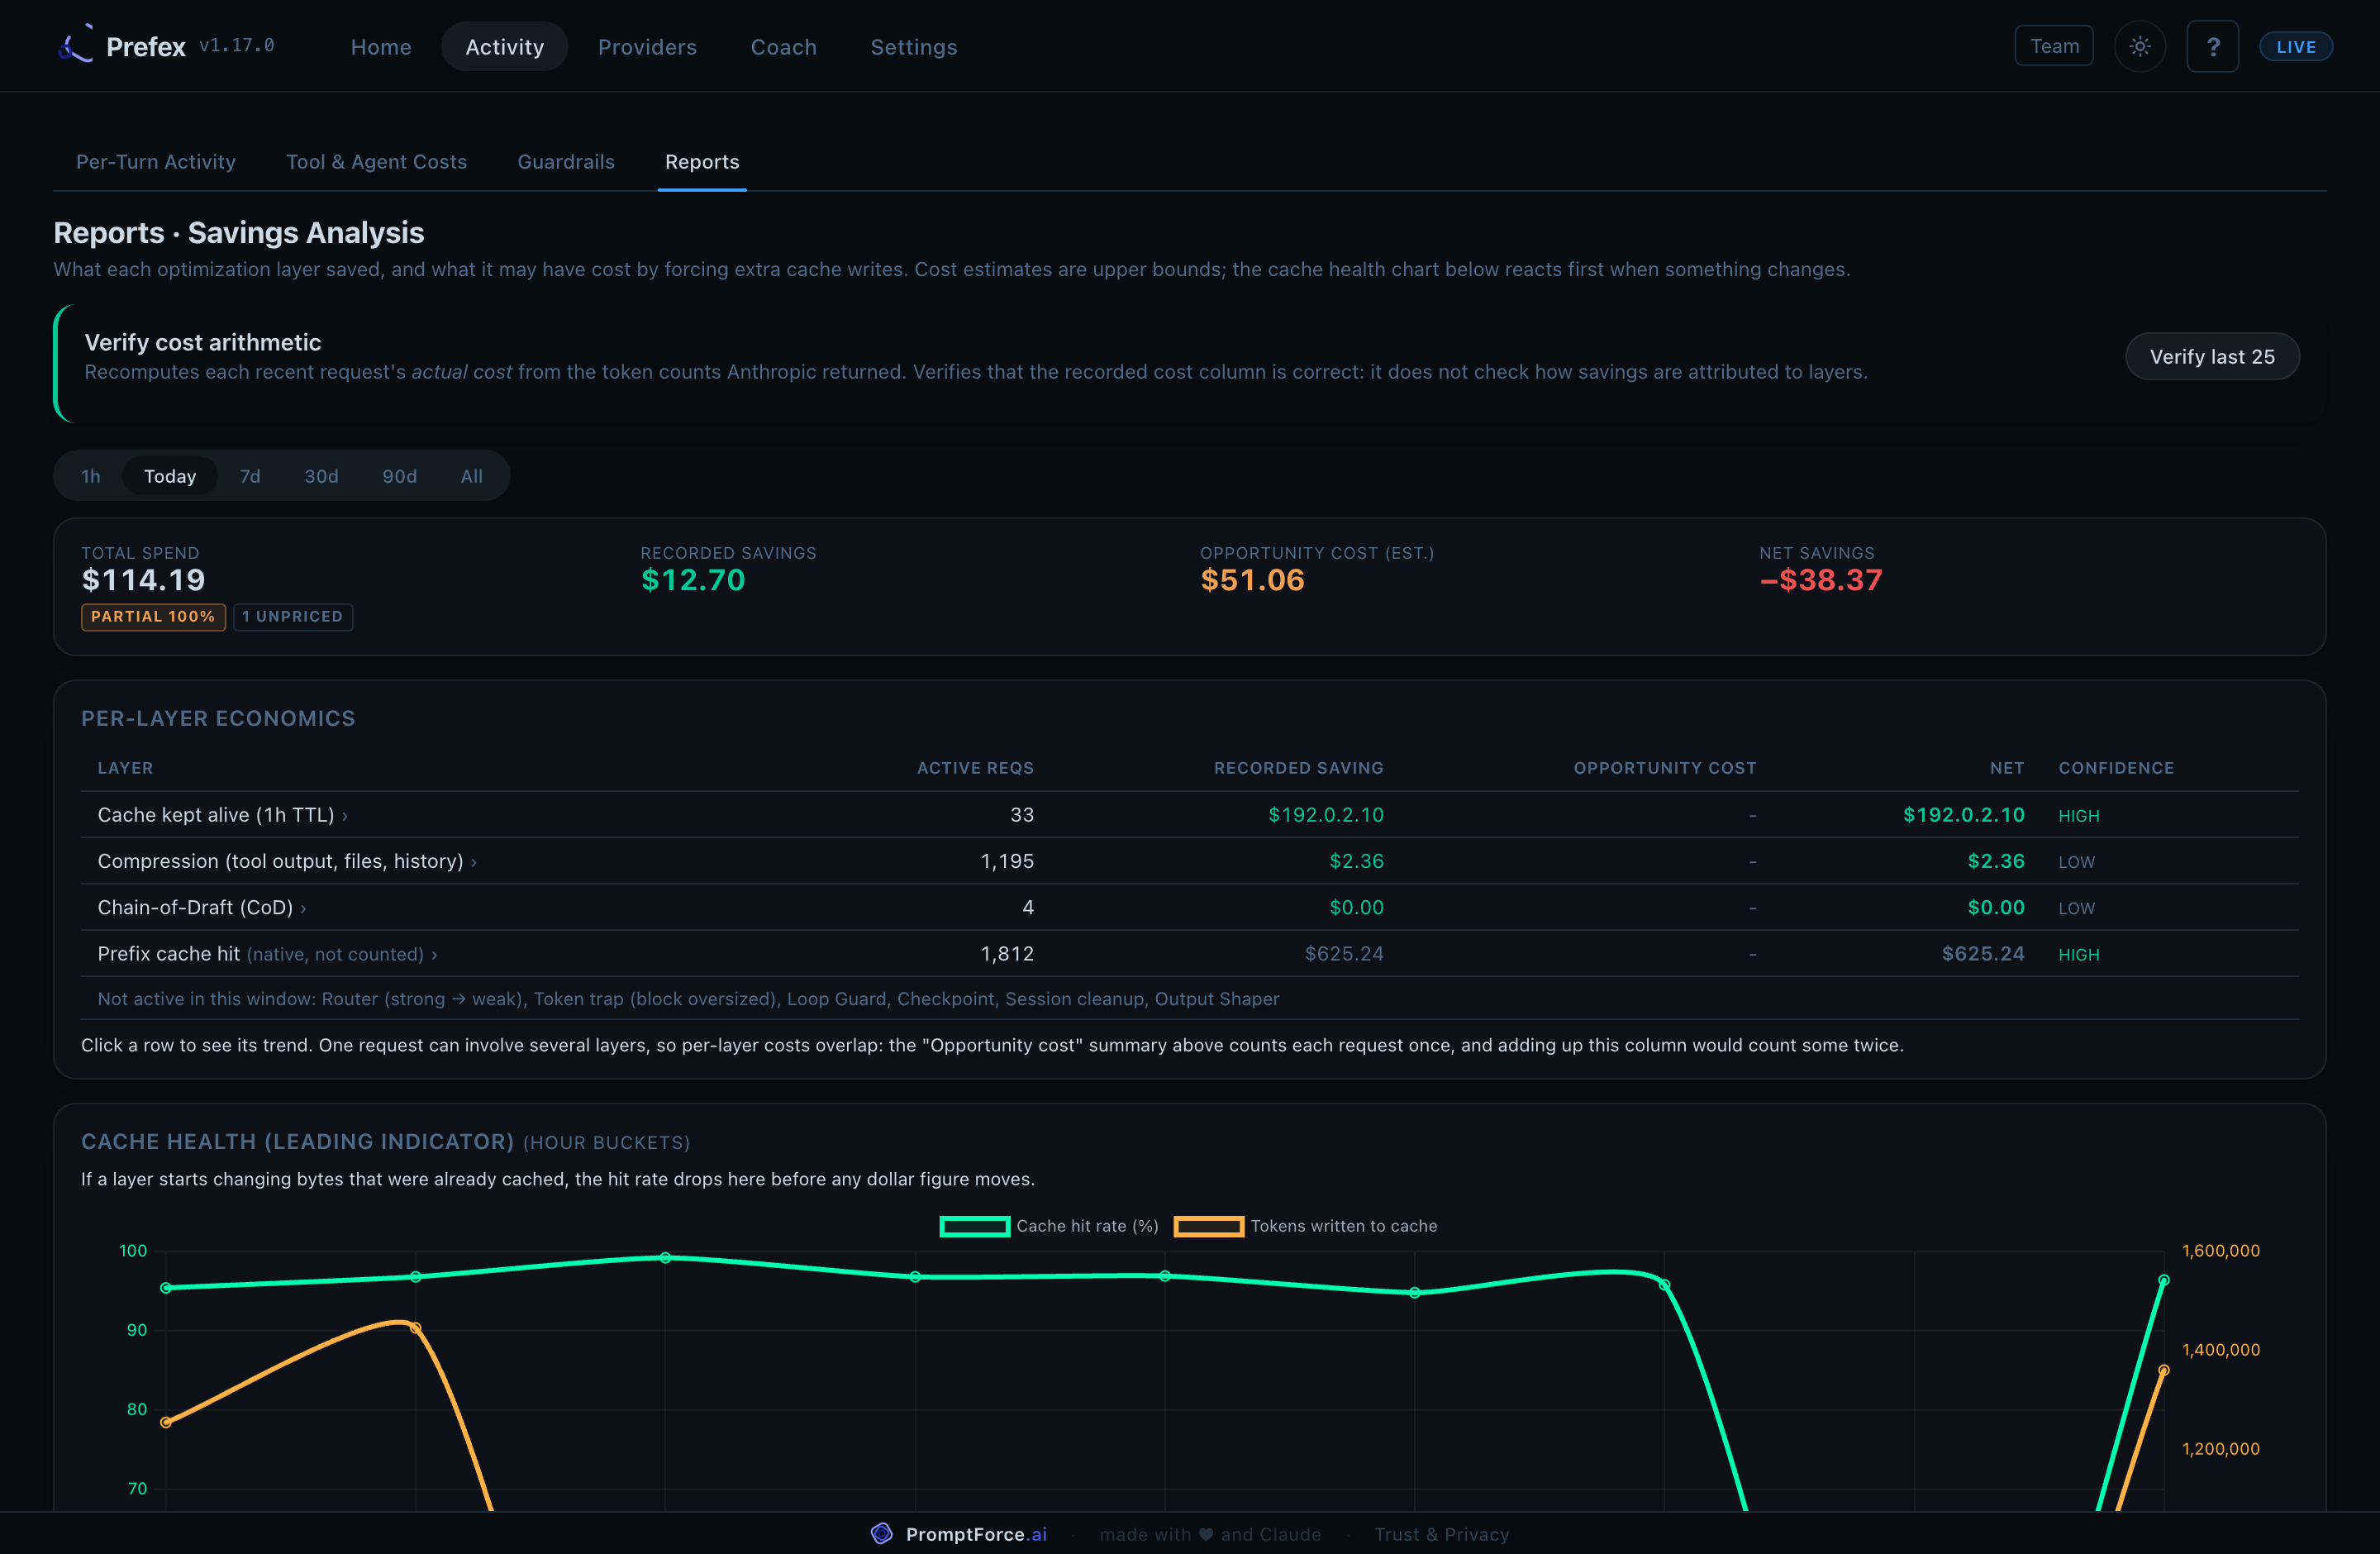
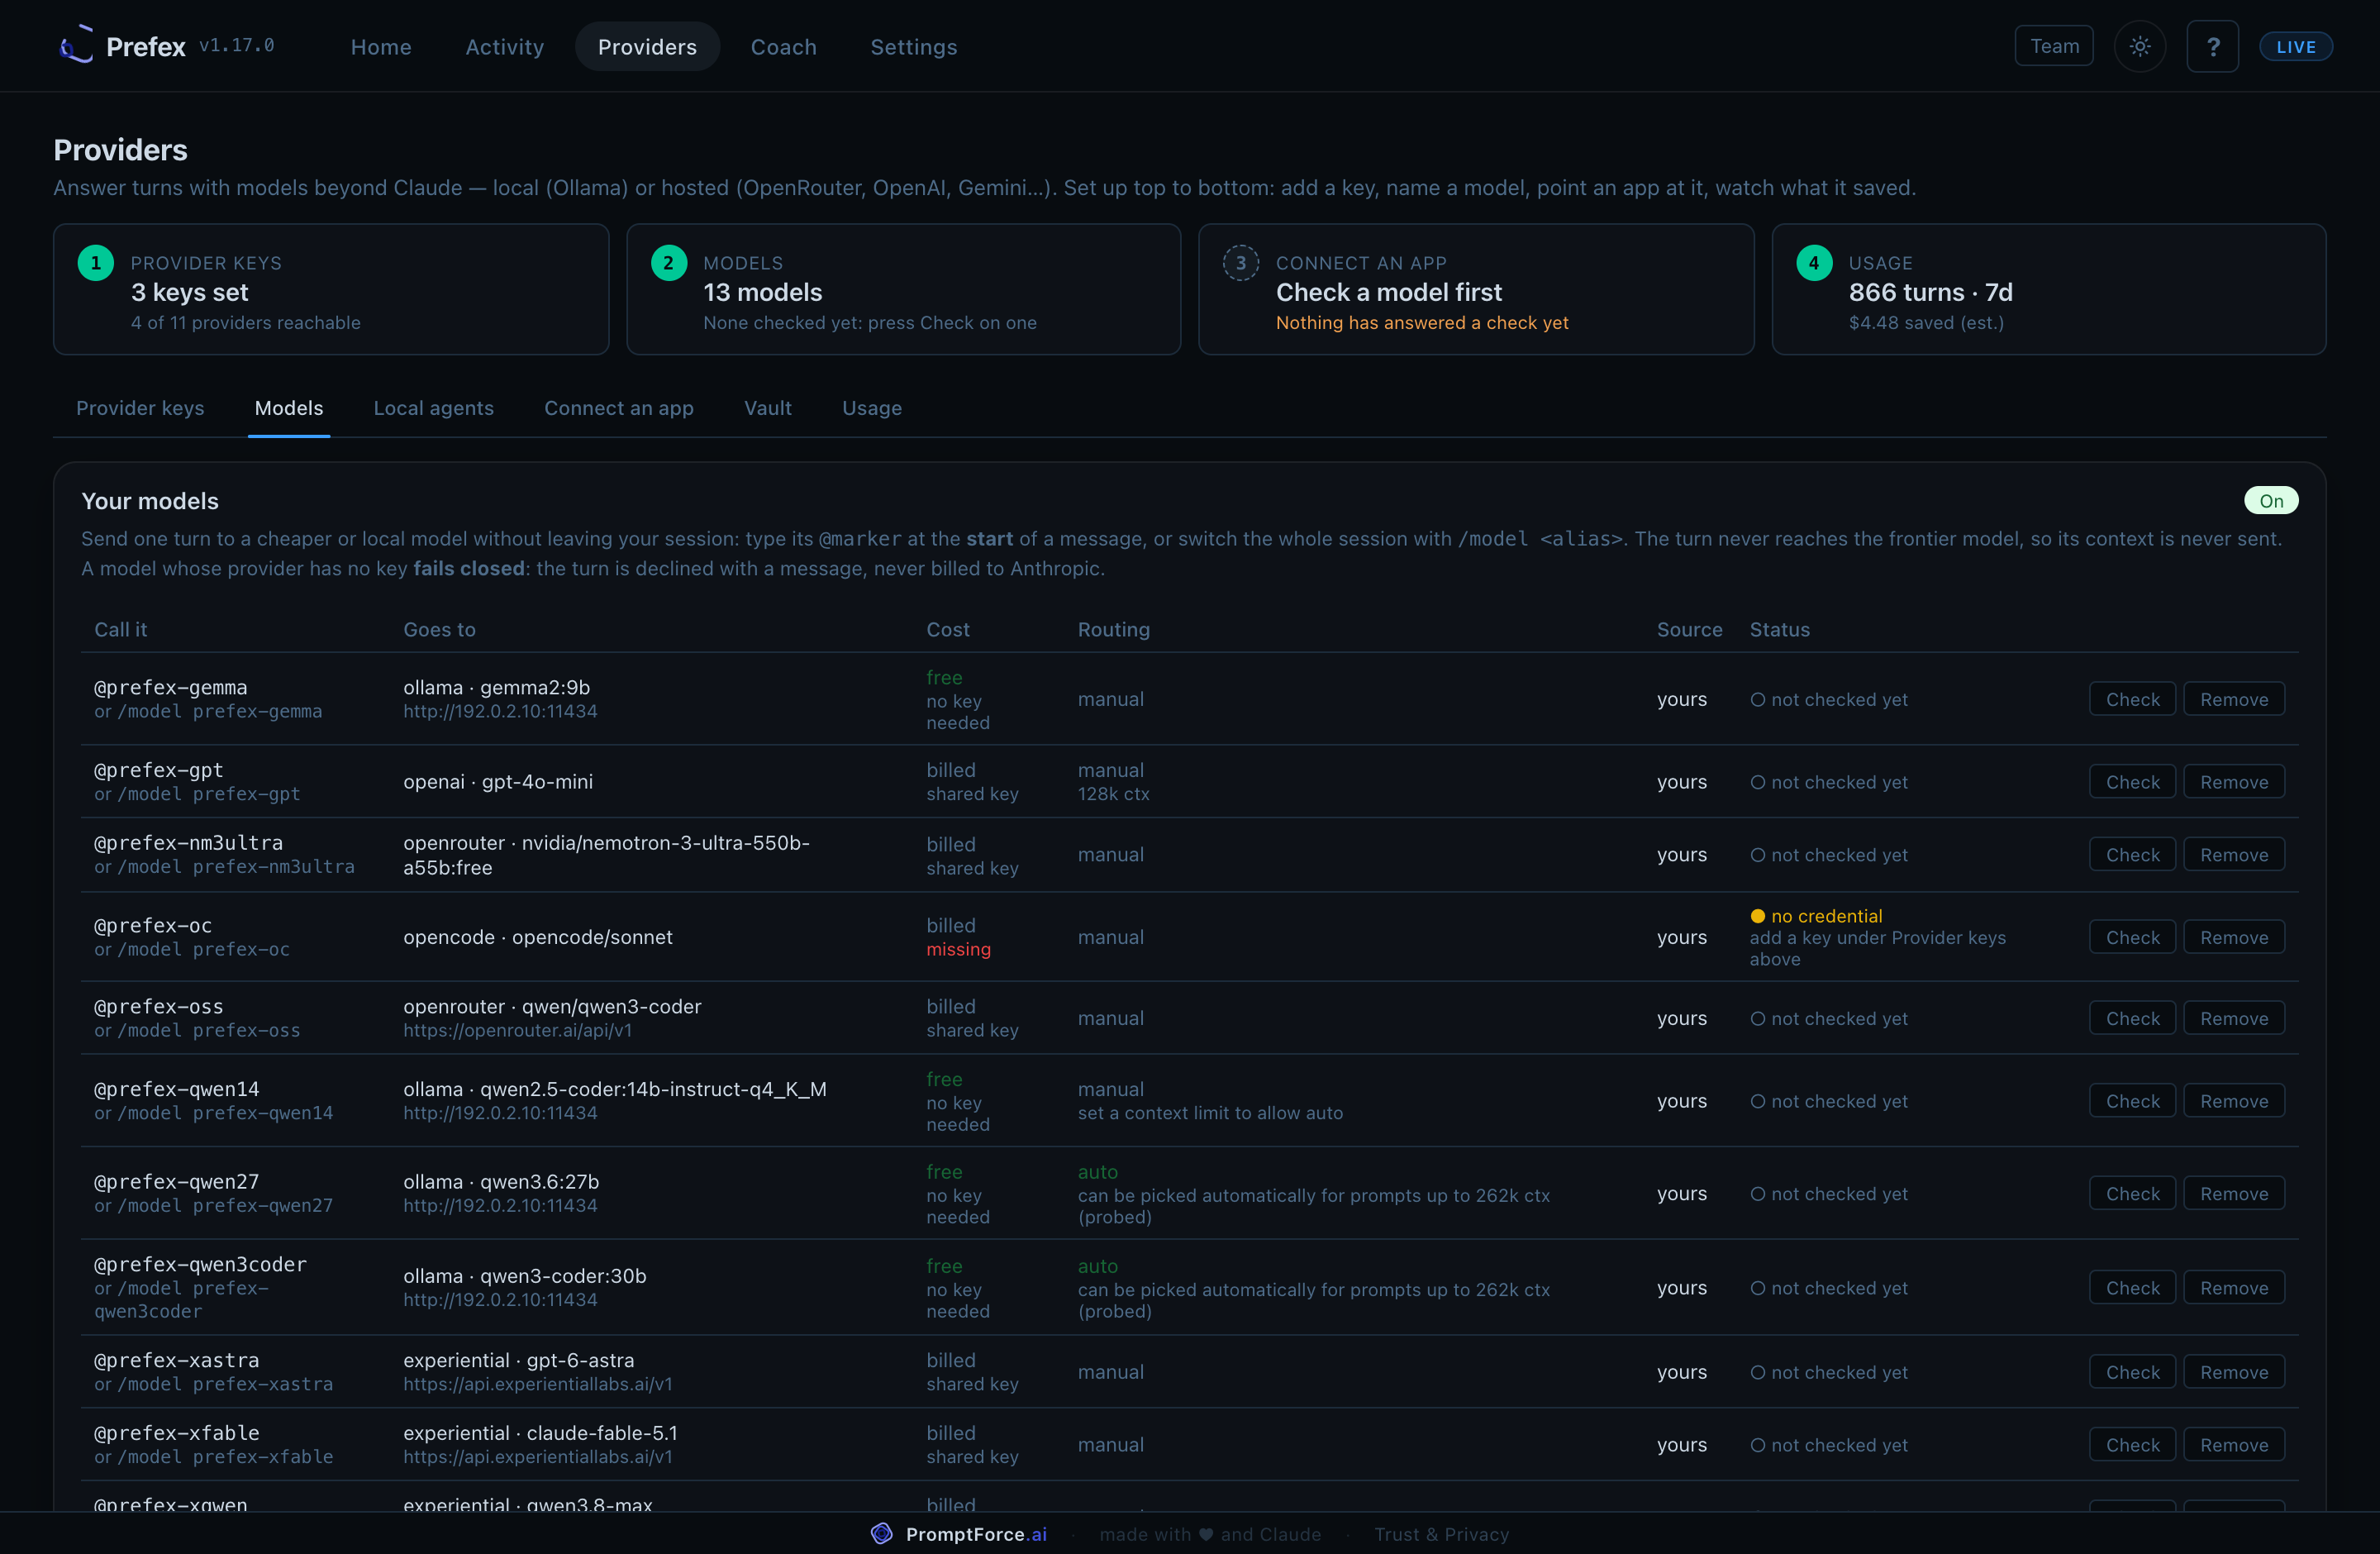
@prefex-gemini, the model catalog and pricing overrides.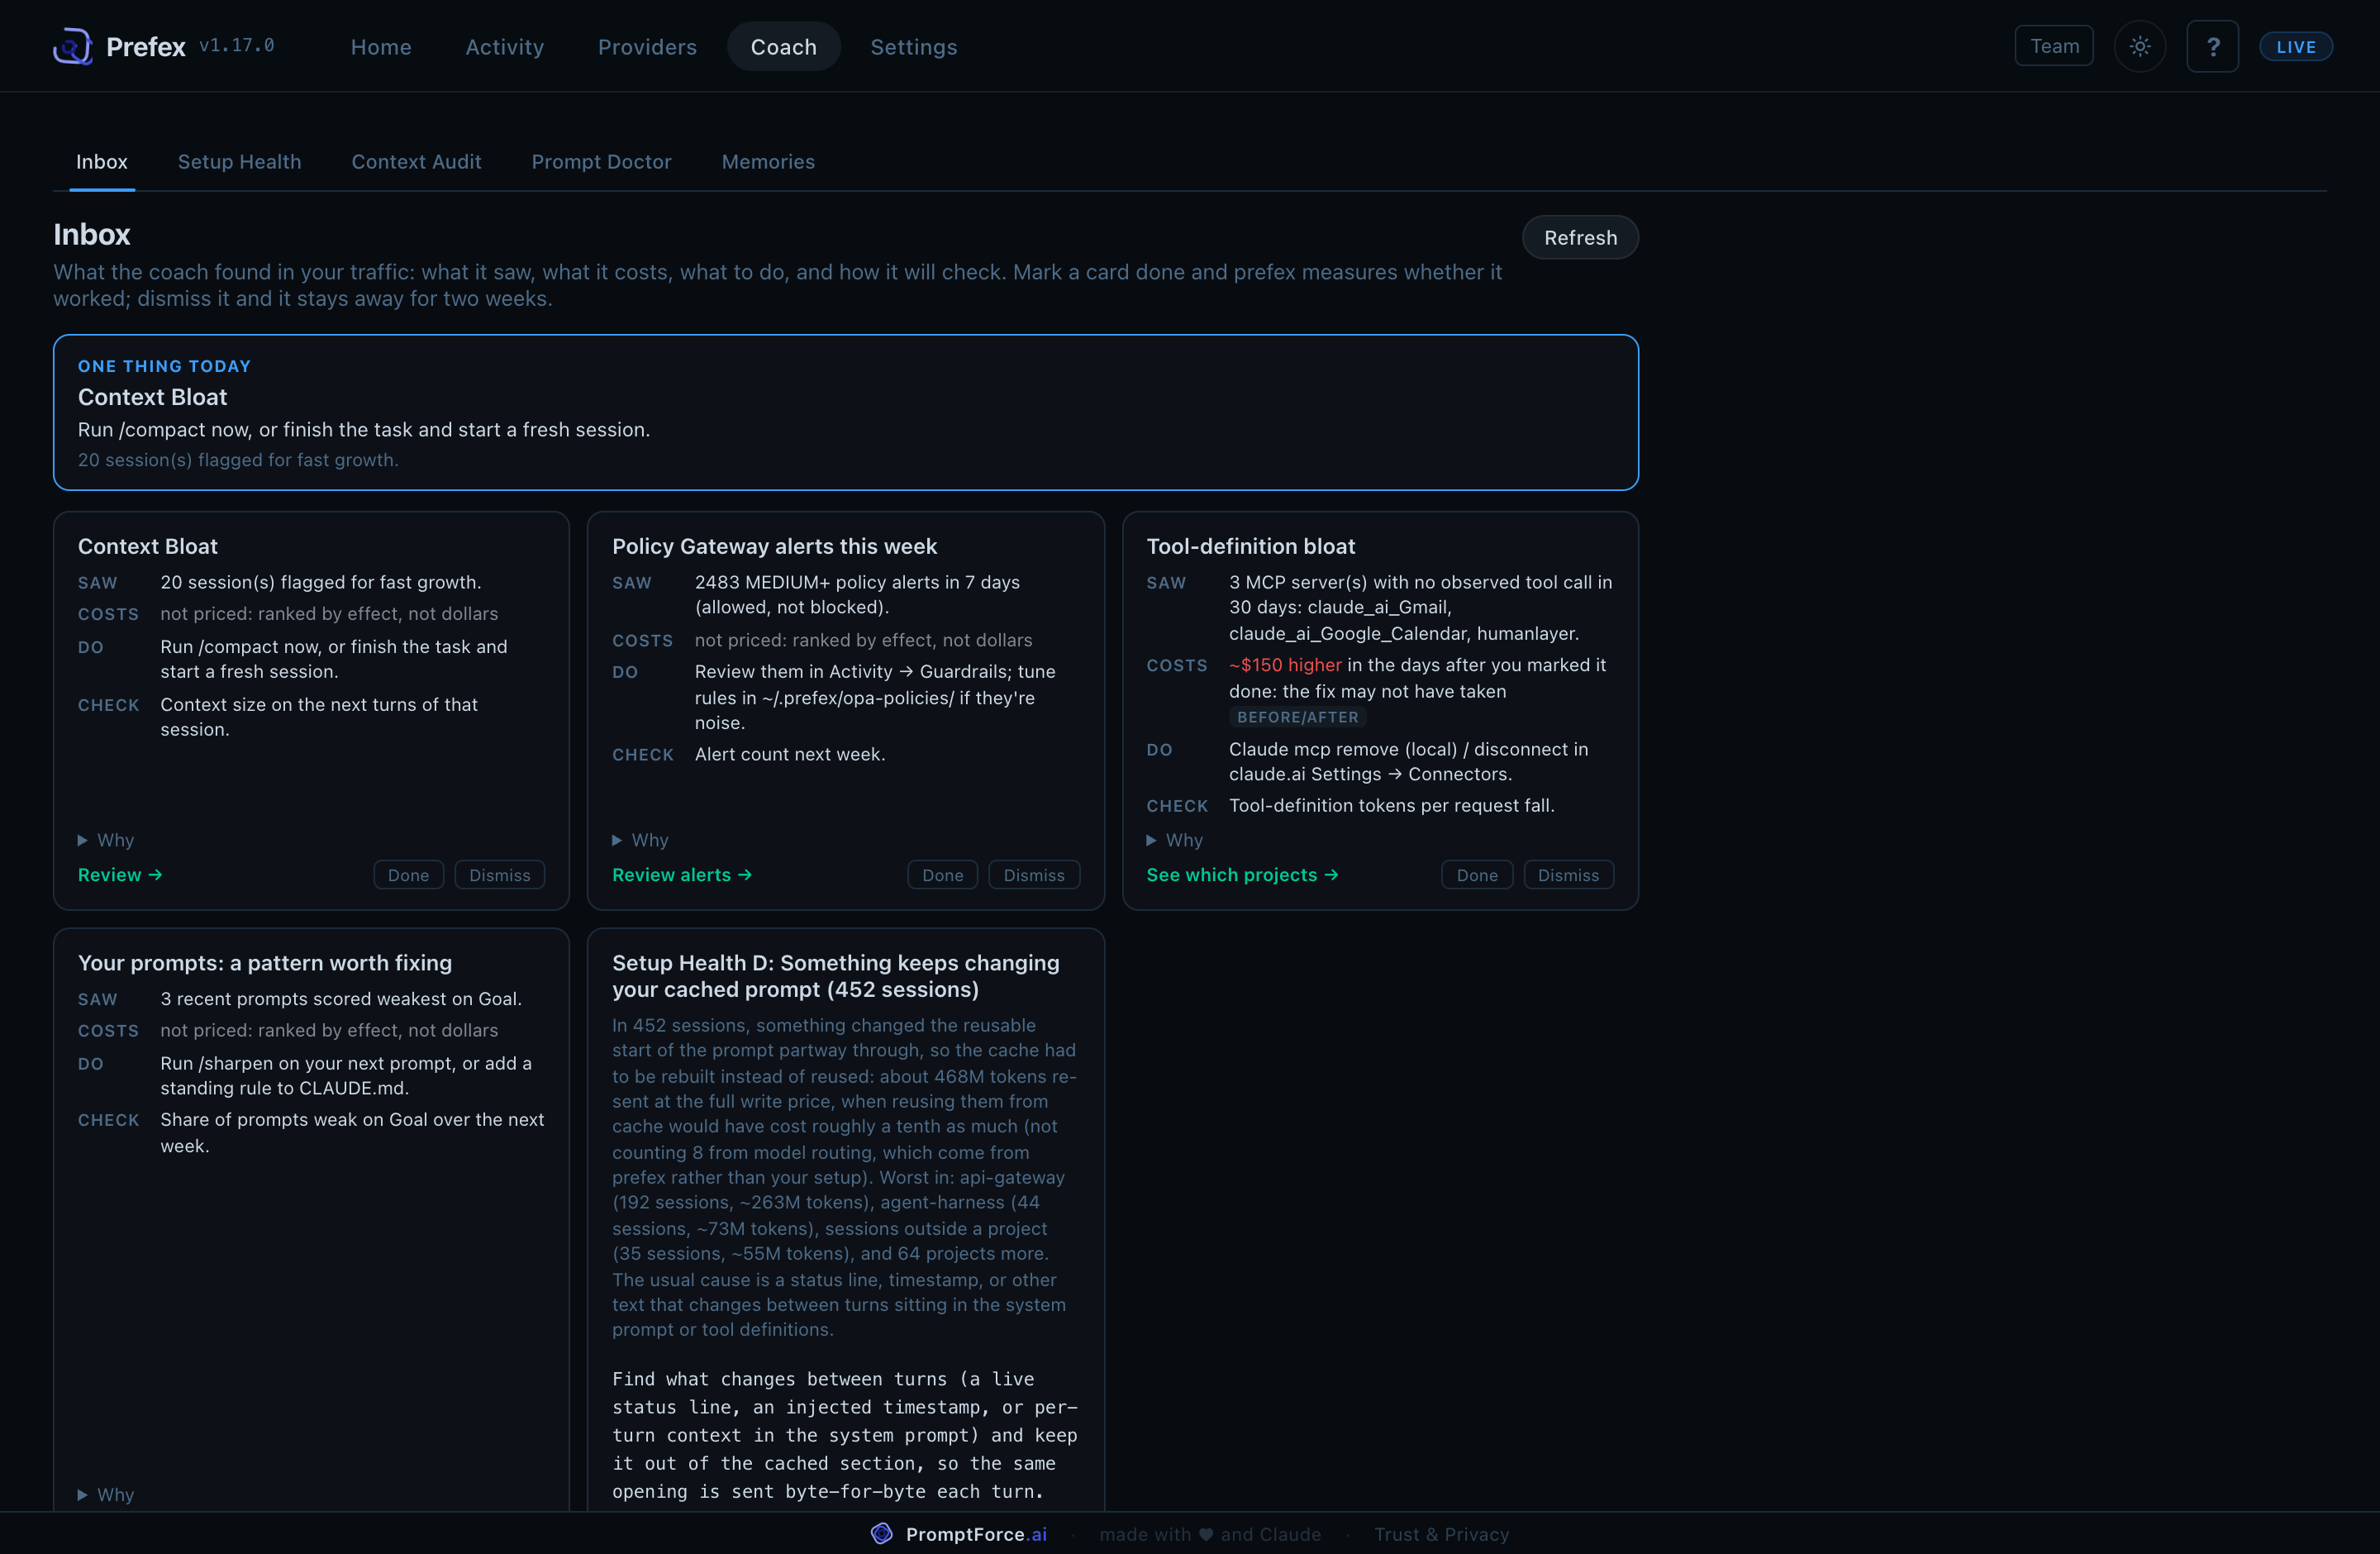
Licence
The free licence runs out by value, not by date: it lasts until prefex has saved you $500 beyond native prompt caching, priced at API rates (the "Saved by prefex" figure on Home). You get a warning at 80%. After that, 15 days of grace, then prefex stops.
On a team hub the same free $500 counts every member's savings, because members' requests go through the hub and its meter. After that, 15 days of grace, then the team needs a Team licence. There is no seat cap while it is free.
Stopping never breaks your tools. Prefex hands Claude Code and Codex back to their direct connection to the provider, lets in-flight requests finish and exits. It never becomes a proxy that refuses requests.
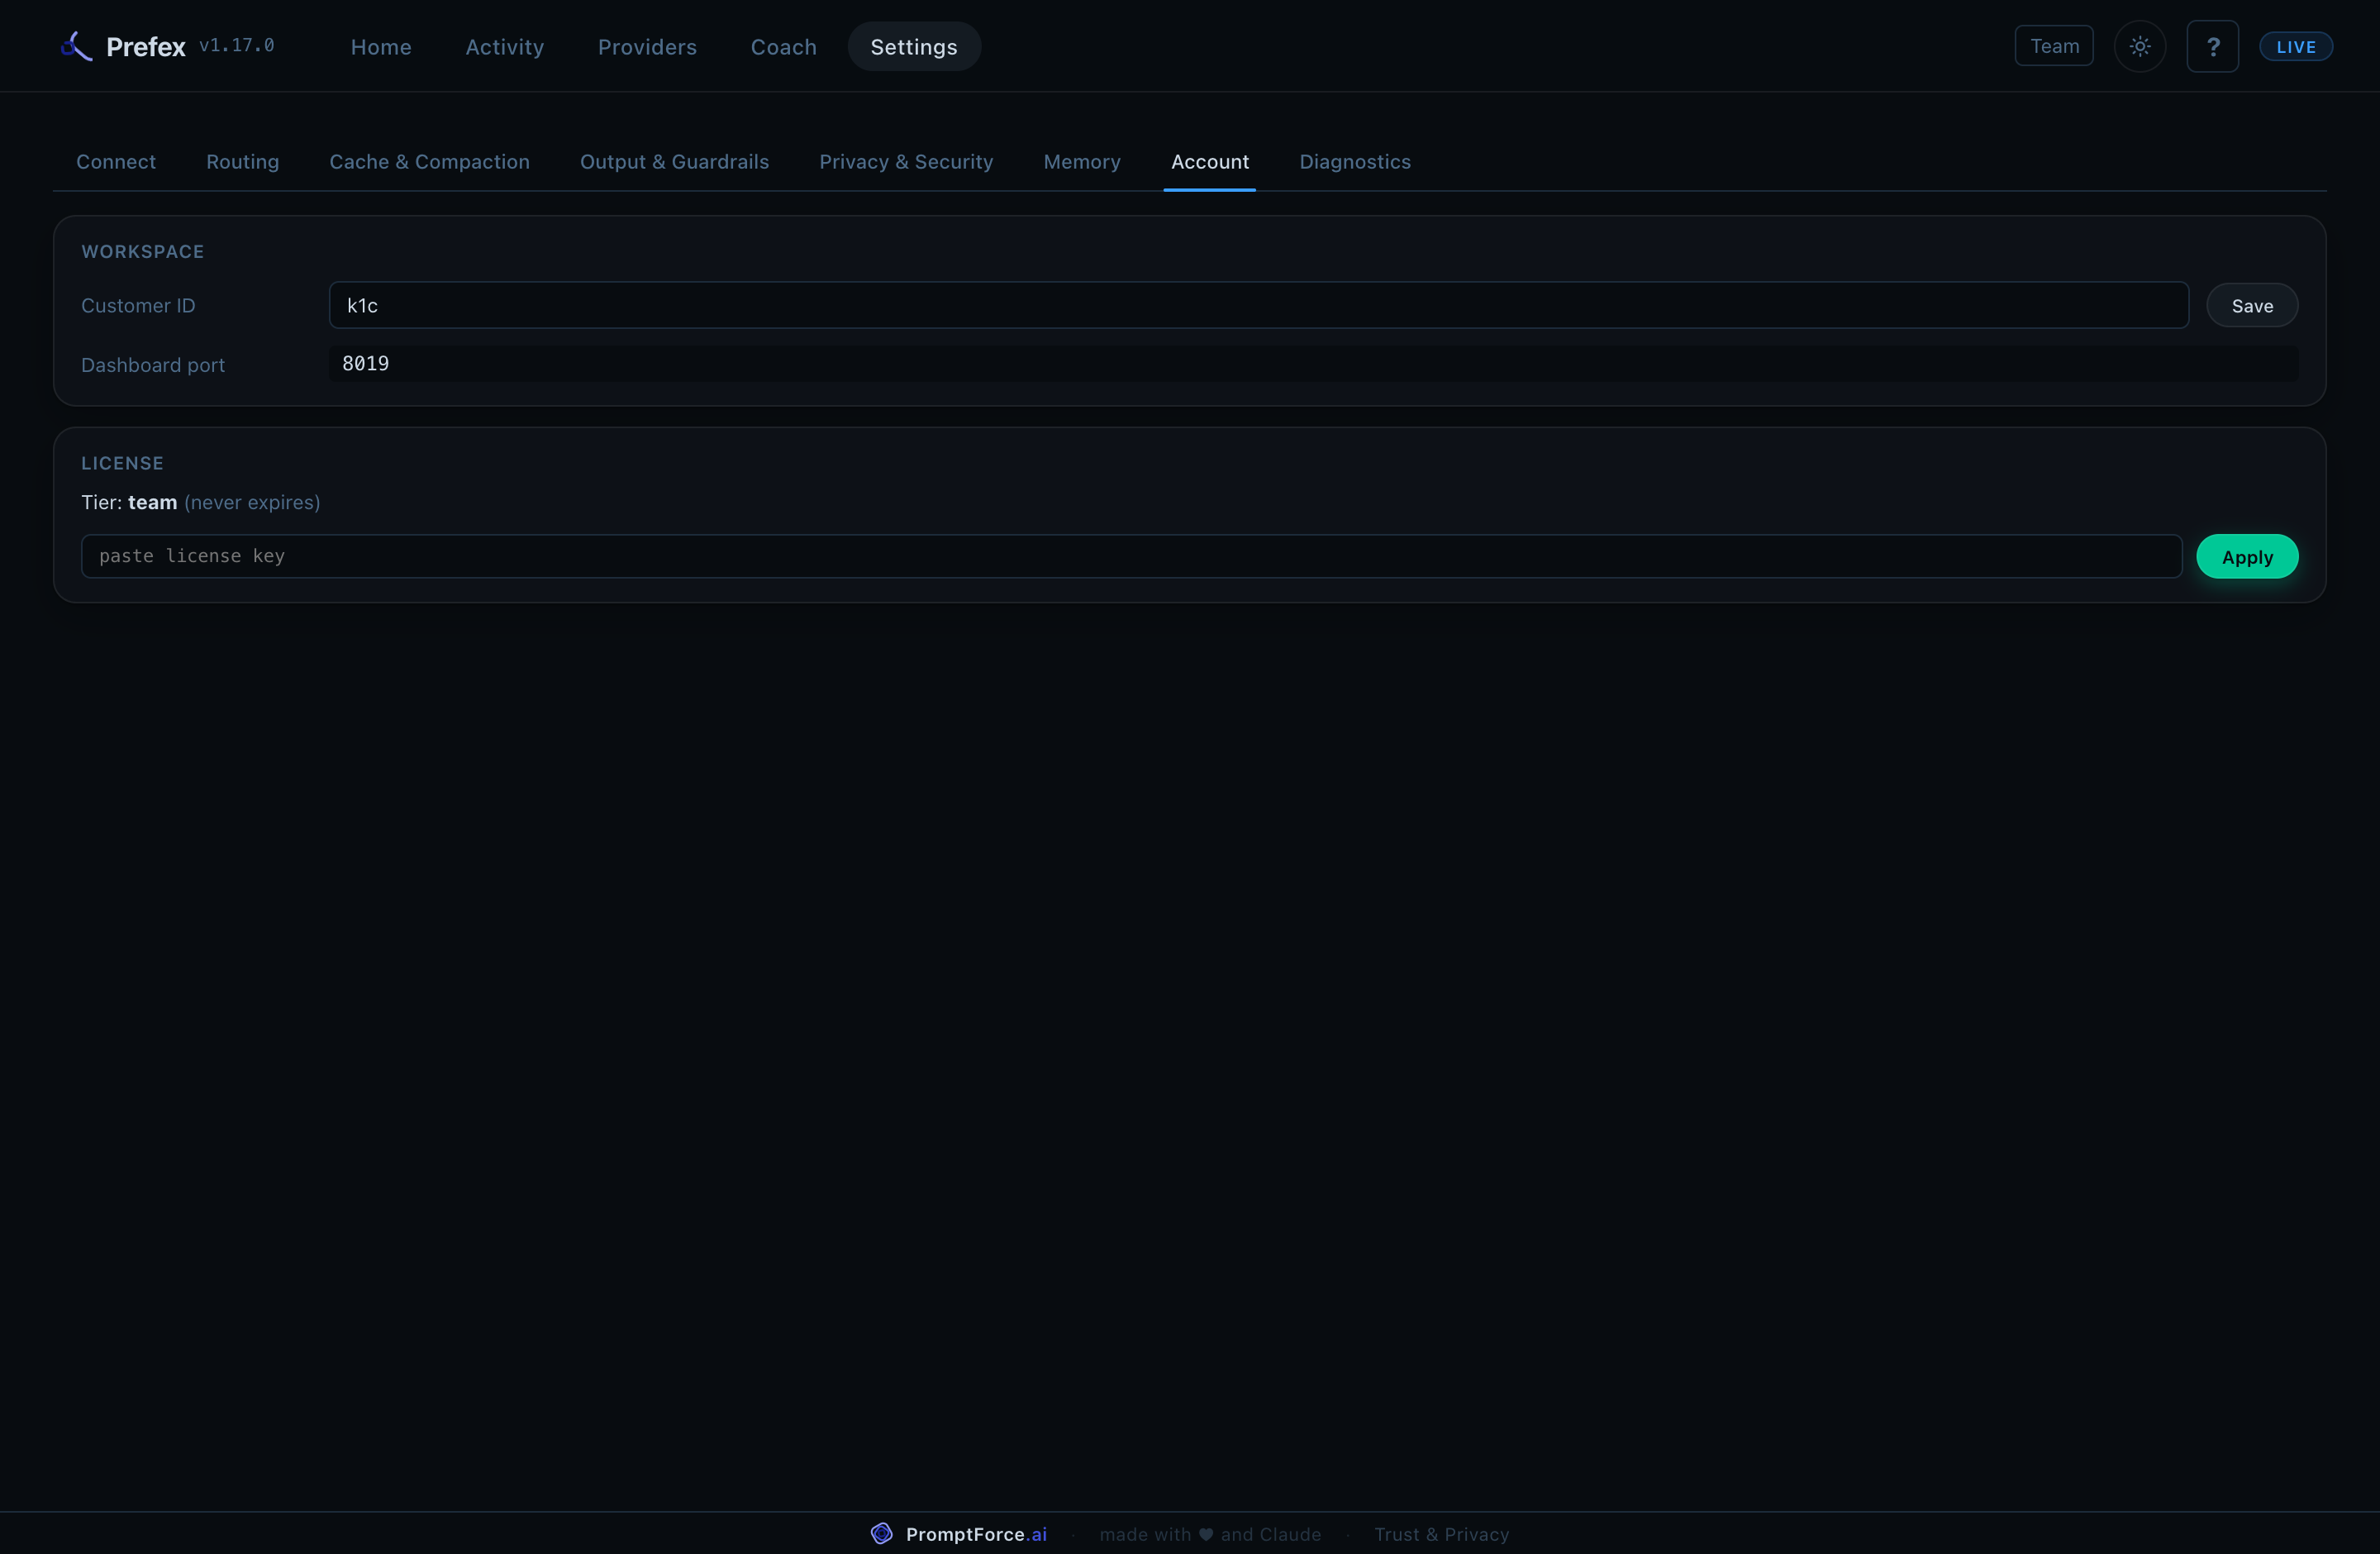
Apply a key in Settings → Account or with prefex license apply <key> (works with the daemon stopped). Keys are issued by hand for now: contact us. A daily licence check sends a salted machine hash and the meter reading, never prompts, keys or email; if it can't reach the server, prefex keeps running.
CLI Reference
prefex start                      # start the daemon and point Claude Code at it
prefex stop --prewarm             # pre-pay each session's cache re-write, then stop and restore settings
prefex reload                     # apply config changes; a bad config is refused, the last good one keeps serving
prefex status                     # what's running, which features are on
prefex toggle <feature> on|off    # switch a feature (works with the daemon down)
prefex wrap <tool> [-- args]      # claude | codex | aider | copilot | opencode | cursor
prefex install --clients claude_code,codex   # connect clients permanently
prefex update                     # install the latest release
prefex license [apply <key>]      # licence state, or apply a key
prefex pricing show <model>       # the rate prefex uses for a model
prefex export [--text] [--format csv]   # your record to a folder: requests, turn costs, audit log; --text adds prompts and memory
prefex forget                     # delete your record from this machine (keys, team settings and licence stay)
prefex provenance turns --json    # cost per ReadyBase turn, for ReadyBase and the PromptForce app
prefex team status [--json]       # on a member machine: hub, certificate, seat and routing, link by link
prefex team failover on|off       # hub down: go direct with your own sign-in, then back
prefex team rotate-admin-token    # on the hub: new admin token; member seats keep working
prefex encoder install            # the local routing encoder (macOS Apple silicon, Linux)
prefex report -days 30            # savings report
prefex help                       # everything else
Always stop with prefex stop, never by killing the process: if the daemon dies while Claude Code still points at it, requests fail until you run prefex start or prefex stop.
Uninstall
prefex uninstall
Stops the daemon, removes login autostart, and restores the Claude Code and Codex settings prefex changed. Your data in ~/.prefex/ is kept; add --purge to delete it too, or --dry-run to see the plan first.